On this article, you’ll be taught the conceptual and sensible variations between retrieval and reminiscence in agentic AI techniques, and easy methods to mix each successfully.
Matters we’ll cowl embrace:
- What separates retrieval from reminiscence, and why the excellence issues for long-running brokers.
- How retrieval pipelines and reminiscence techniques are every constructed, illustrated with a concrete labored instance.
- How you can mix retrieval and reminiscence right into a single, efficient agent structure.
Introduction
An AI agent that may’t bear in mind its earlier interactions is just not very useful. Each giant language mannequin has a hard and fast context window, and as soon as a dialog, a set of instrument outputs, or a pile of retrieved paperwork grows previous that restrict, one thing needs to be dropped, summarized, or fetched recent. Builders constructing long-running brokers run into this always. The agent re-asks questions it already answered, contradicts choices it made earlier, or fails to acknowledge {that a} doc it wants even exists.
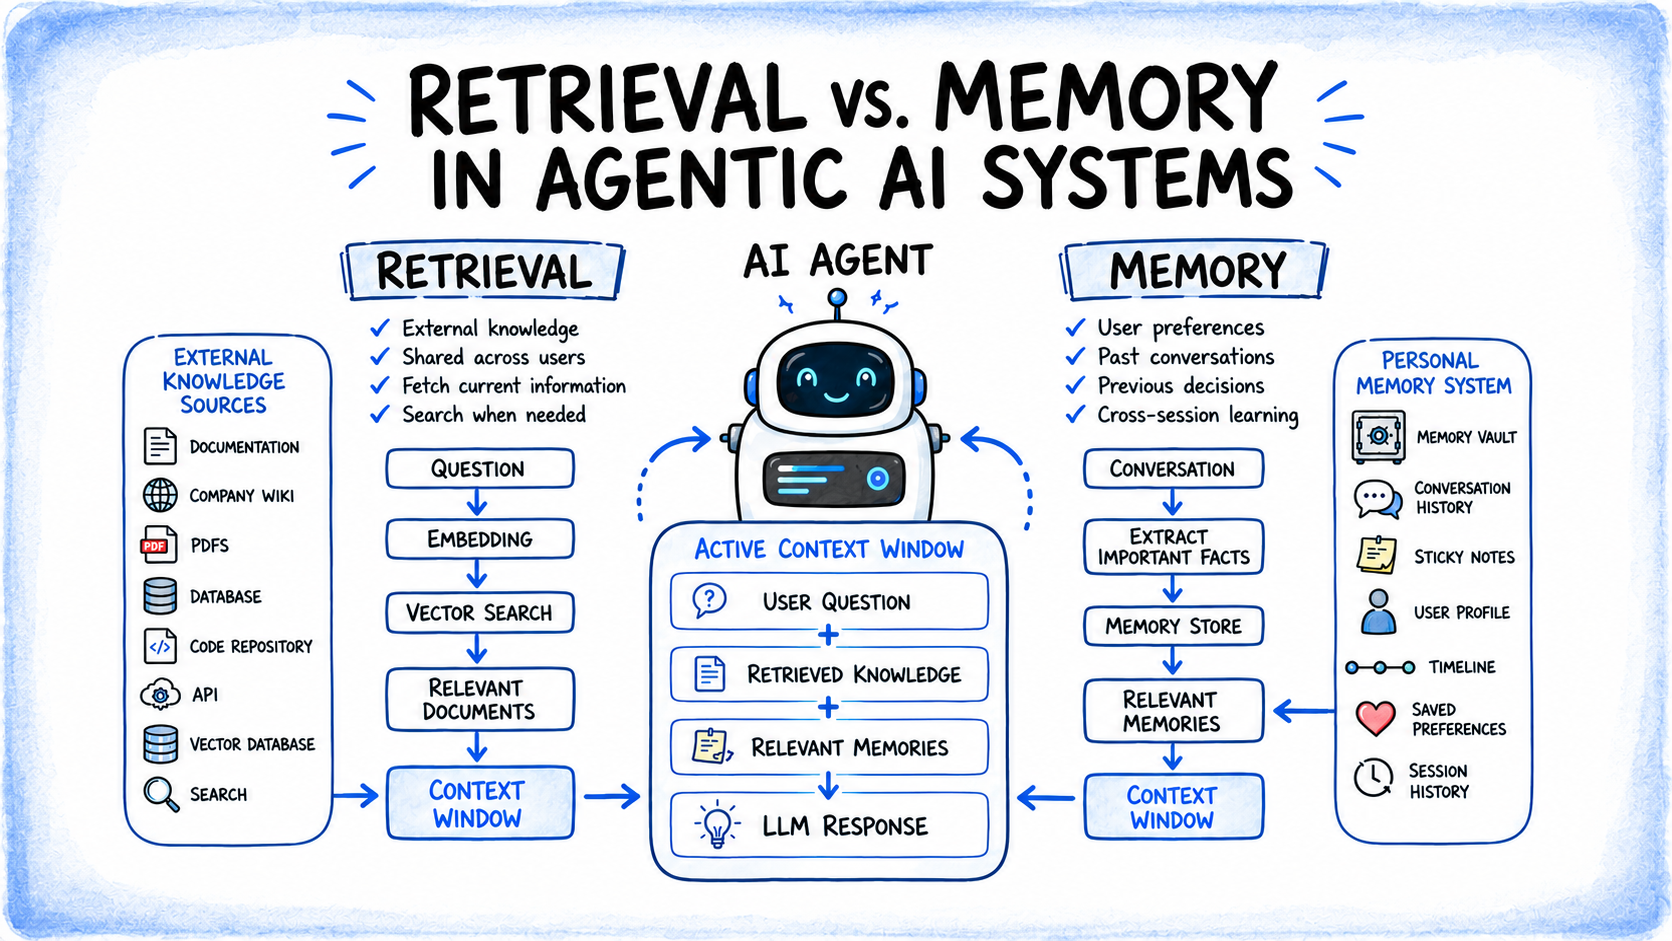
Retrieval and reminiscence are the 2 mechanisms that handle this, and so they resolve completely different halves of the issue. Retrieval pulls in exterior data the mannequin was by no means educated on and mustn’t have to hold by default, reminiscent of documentation, code, and database data. Reminiscence persists what the agent itself has realized or executed, throughout a session or throughout many, so it isn’t ranging from zero each time. Complicated the 2, or constructing just one, is the place a whole lot of agent architectures break down. This text covers:
- What separates retrieval from reminiscence at a conceptual degree
- How a retrieval pipeline and a reminiscence system are every constructed, with a labored instance
- A side-by-side comparability of the 2
- How you can mix each right into a single, efficient agentic system
We begin with why the break up exists within the first place.
Understanding Why Context Forces a Break up
A context window is the overall set of tokens the mannequin can see without delay: system immediate, dialog historical past, instrument outputs, something inserted forward of time. It’s finite, and each token in it will get attended to on each ahead go, so merely making the window larger doesn’t scale the way in which it sounds prefer it ought to. Context engineering has emerged because the self-discipline of curating and managing that restricted useful resource, treating it as the total state out there to the mannequin at a given second, not only a place to stuff directions.
Provided that constraint, an agent has two varieties of data it wants however can’t maintain completely in context:
- Data that exists exterior the mannequin and out of doors the present dialog, reminiscent of a data base, a codebase, or a set of coverage paperwork. That is what retrieval handles.
- Data the agent generated or realized itself, that should outlive the present context window, reminiscent of a call made ten turns in the past or a truth a couple of particular consumer. That is what reminiscence handles.
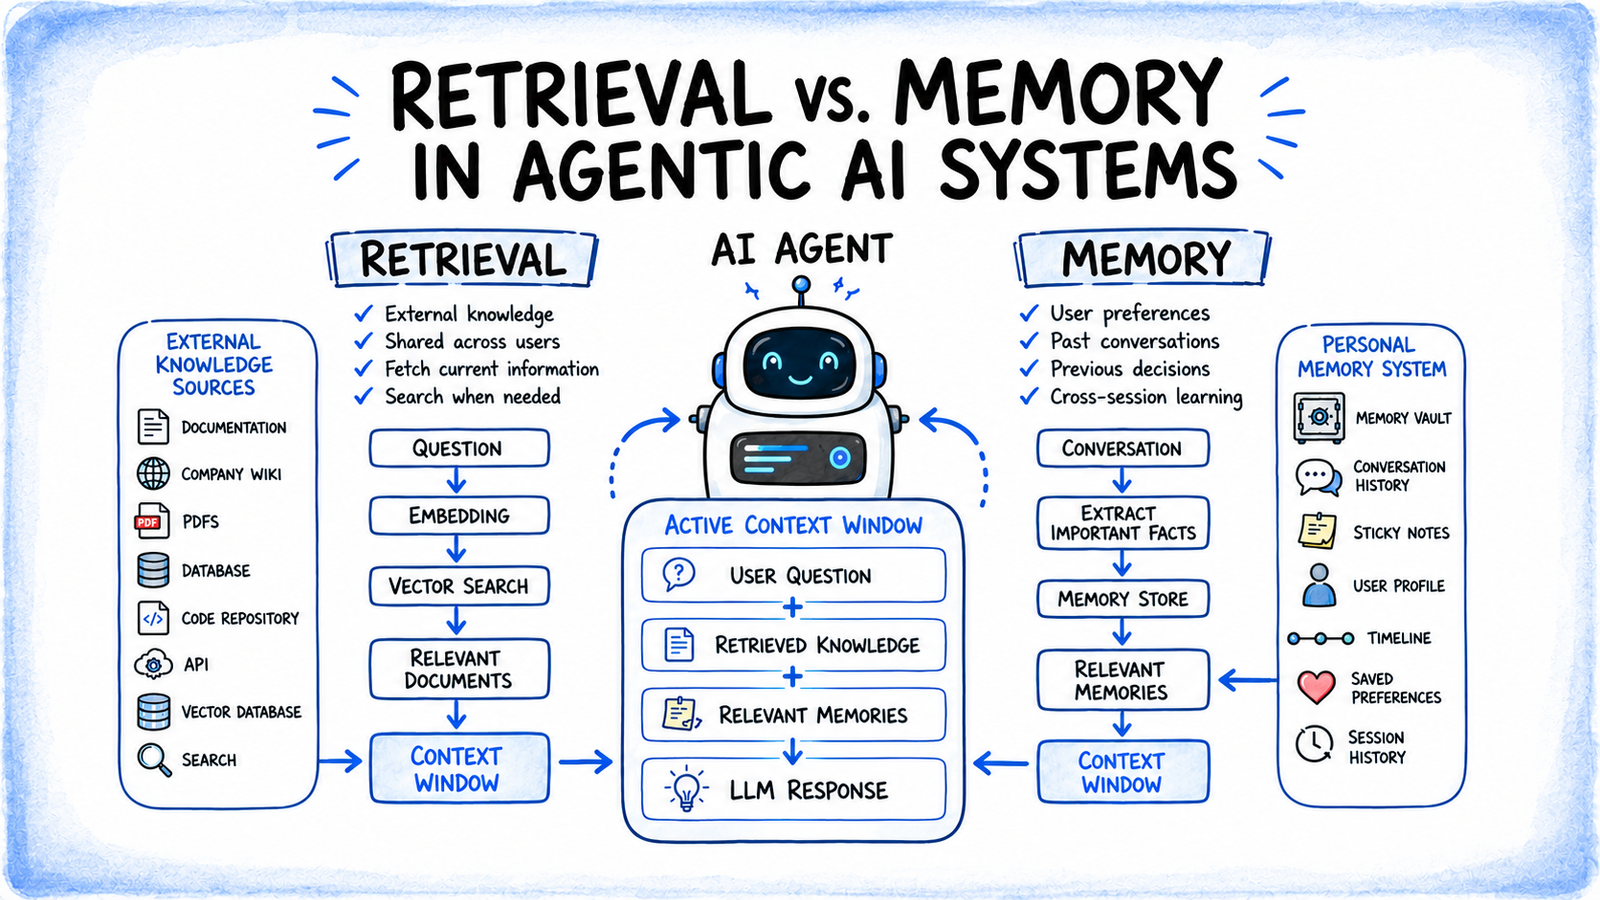
Each get carried out with comparable instruments: embeddings, vector search, structured shops. The important thing distinction is what they retailer and the place the knowledge comes from. Retrieval searches a corpus exterior the agent, whereas reminiscence shops data from the agent’s personal interactions and previous actions.
Defining Retrieval in Agentic Techniques
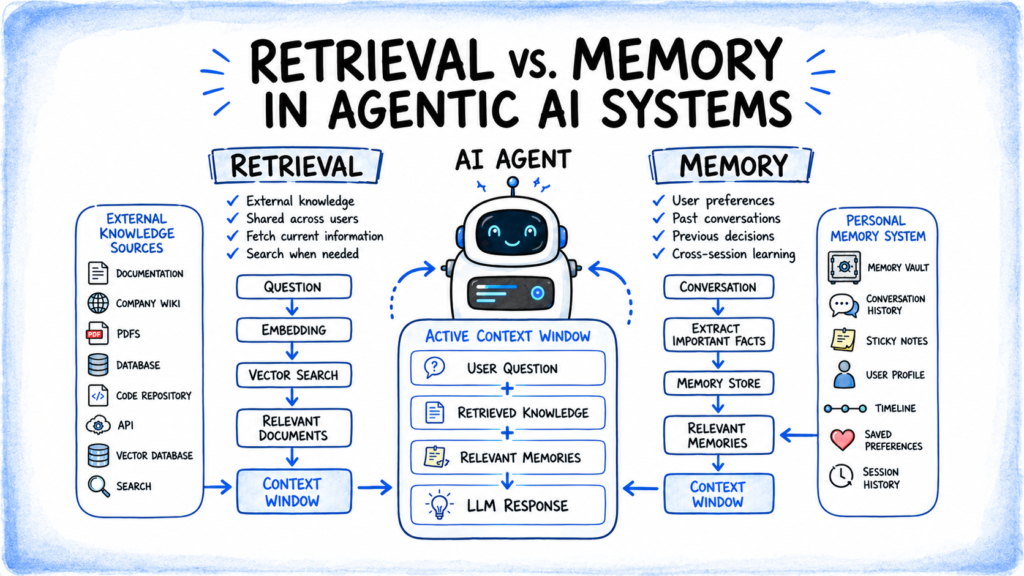
Retrieval is how an agent solutions “what does the world learn about this that I don’t have in my weights or my present context.” The commonest implementation is retrieval-augmented era, or RAG:
- Supply paperwork get chunked into passages sufficiently small to be helpful.
- Every chunk is transformed into an embedding and saved in a vector index.
- At question time, the incoming query is embedded the identical method, and the index returns the closest matches.
- These matches get inserted into the immediate alongside the consumer’s query.
This sample usually runs on managed datastores with an orchestration layer that ties the retrieval step into the remainder of the agent’s reasoning — the strategy behind most retrieval-augmented era architectures in manufacturing at this time. The corpus itself is shared — each consumer asking about the identical product documentation hits the identical index — and it’s refreshed by itself schedule, unbiased of any particular person dialog.
Defining Reminiscence in Agentic Techniques
Reminiscence is how an agent solutions “what have I already realized or executed that I would like to hold ahead.” It splits into two layers that behave in a different way:
- Brief-term reminiscence is the operating session state: the dialog thus far, plus something the agent has written to a scratchpad through the present job. It’s low cost, and it disappears when the session ends.
- Lengthy-term reminiscence persists throughout periods. It has to reply a more durable query than retrieval does: not simply “what’s related,” however “what’s value conserving within the first place.”
Some agent reminiscence techniques robotically extract helpful information, preferences, and context from conversations and retailer them for later use. Initially of a brand new session, the agent can question that reminiscence very like it might question a retrieval index, however the outcomes are particular to a consumer, job, or agent fairly than a shared doc corpus. When designing this layer, groups can discover completely different agent reminiscence methods and agent reminiscence frameworks relying on what they should retailer and retrieve.
A fast labored instance makes the break up concrete. A buyer messages a help agent a couple of delayed order.
For a delayed order, the agent first checks its reminiscence for the shopper’s earlier historical past. It finds a observe from three weeks in the past saying they like e mail follow-up and {that a} comparable transport concern was resolved with a partial refund. That’s reminiscence, as a result of it comes from the agent’s report of this particular buyer.
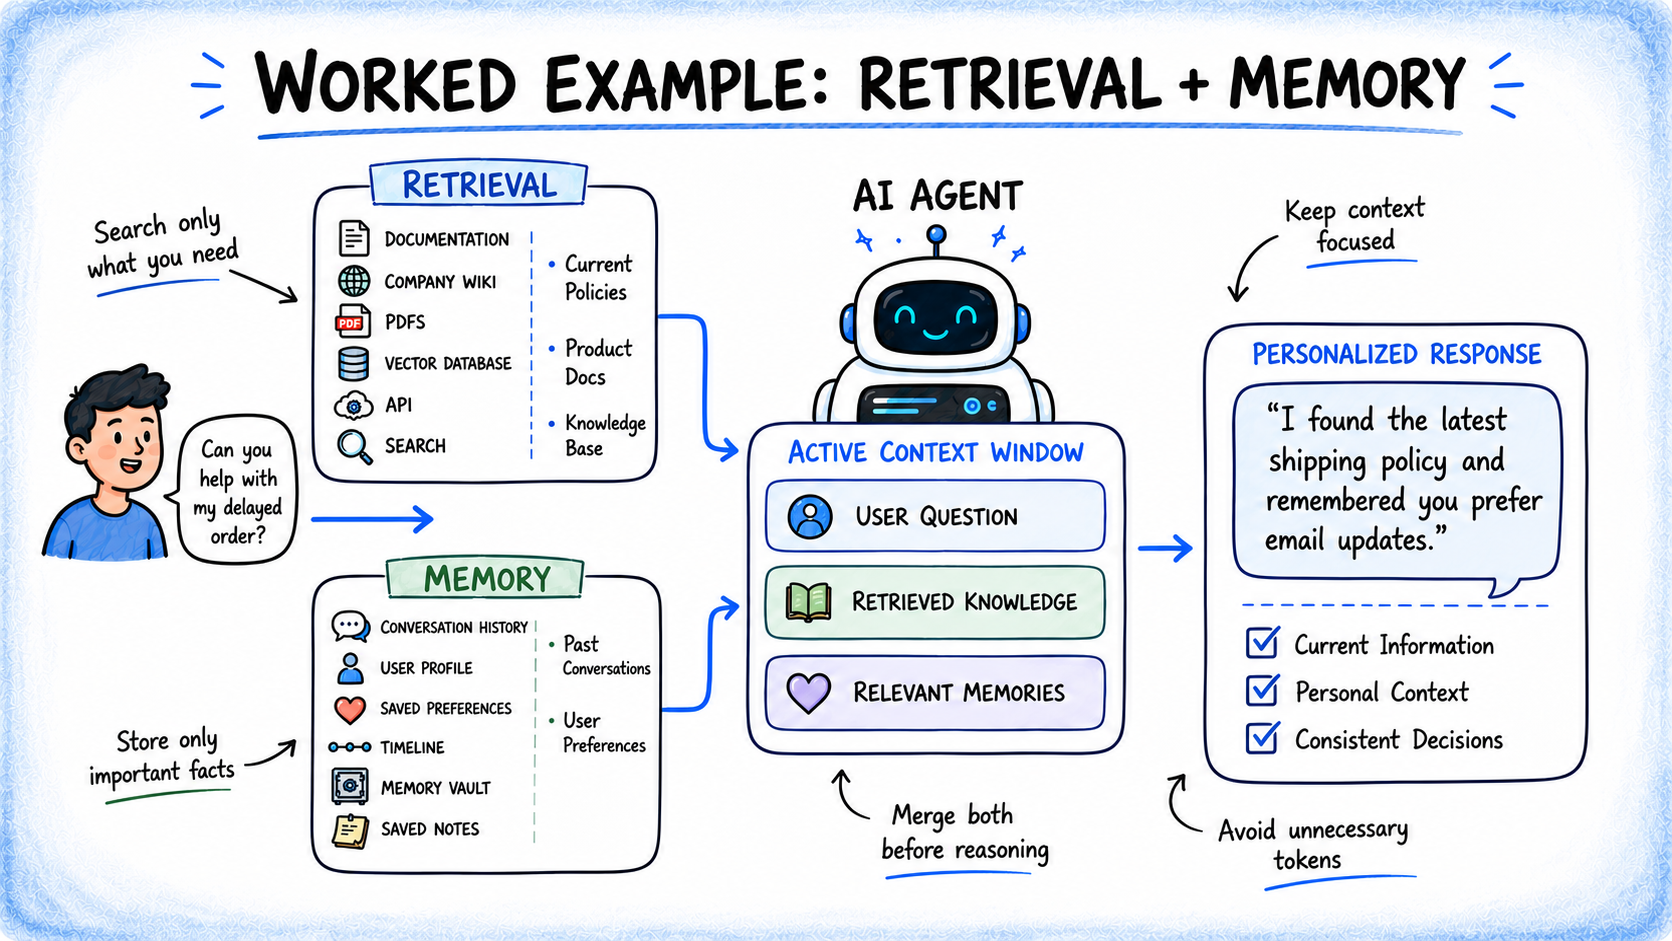
The agent then wants the present transport coverage, which modified final month, so it searches the corporate’s documentation and retrieves the related part. That’s retrieval, as a result of the knowledge comes from an exterior supply and applies to all prospects. Each outcomes are added to the identical immediate, however they reply completely different questions.
Evaluating Retrieval and Reminiscence
Laid out facet by facet, the variations between retrieval and reminiscence are simpler to see at a look:
| Dimension | Retrieval | Reminiscence |
|---|---|---|
| Supply of data | Exterior corpus the agent didn’t create | The agent’s personal previous interactions or reasoning |
| Scope | Shared throughout all customers and periods | Particular to a consumer, job, or session |
| What it solutions | “What does the world learn about this?” | “What have I already realized or executed?” |
| Freshness mechanism | Re-index the corpus on a schedule or on write | Consolidate, replace, or expire saved information |
| Typical failure mode | Stale or lacking paperwork within the index | Contradictory or outdated information a couple of consumer |
| Value sample | Learn-heavy; one lookup per question | Learn and write; extraction runs after each interplay |
The failure modes listed within the desk above clarify why an agent constructed with solely one of many two tends to interrupt in predictable methods, and why most working techniques find yourself needing each.
Combining Retrieval and Reminiscence into an Efficient System
An agent with retrieval however no reminiscence re-derives the identical conclusions each session and may’t personalize something. An agent with reminiscence however no retrieval is aware of its personal historical past however has no method to floor itself in something exterior that historical past; it could possibly’t reply questions on a coverage that modified after its coaching knowledge ended. Getting the mixture proper comes down to a couple issues:
- Filtering issues greater than window measurement. Including extra retrieved paperwork or reminiscence entries doesn’t essentially enhance solutions. Past a degree, further context could make solutions worse as a result of the mannequin has to course of and weigh each extra token. Small, focused searches are sometimes simpler than one broad search and may maintain retrieval token-efficient.
- Staleness works in a different way for retrieval and reminiscence. A retrieval index turns into stale when the underlying paperwork change with out being re-indexed. Reminiscence turns into stale when details about a consumer adjustments — reminiscent of a desire or plan — however the saved truth is just not up to date or eliminated.
- Reminiscence provides a write value. Retrieval often includes trying up data when the agent wants it. Reminiscence additionally requires deciding what data is value saving after an interplay, which may add mannequin calls and processing time. This extraction is usually dealt with asynchronously so it doesn’t decelerate the agent’s response.
- The 2 sources must be merged rigorously. Retrieval and reminiscence can return data that overlaps or conflicts. The agent wants clear guidelines for deciding how a lot weight to offer every supply and easy methods to use each in the identical context.
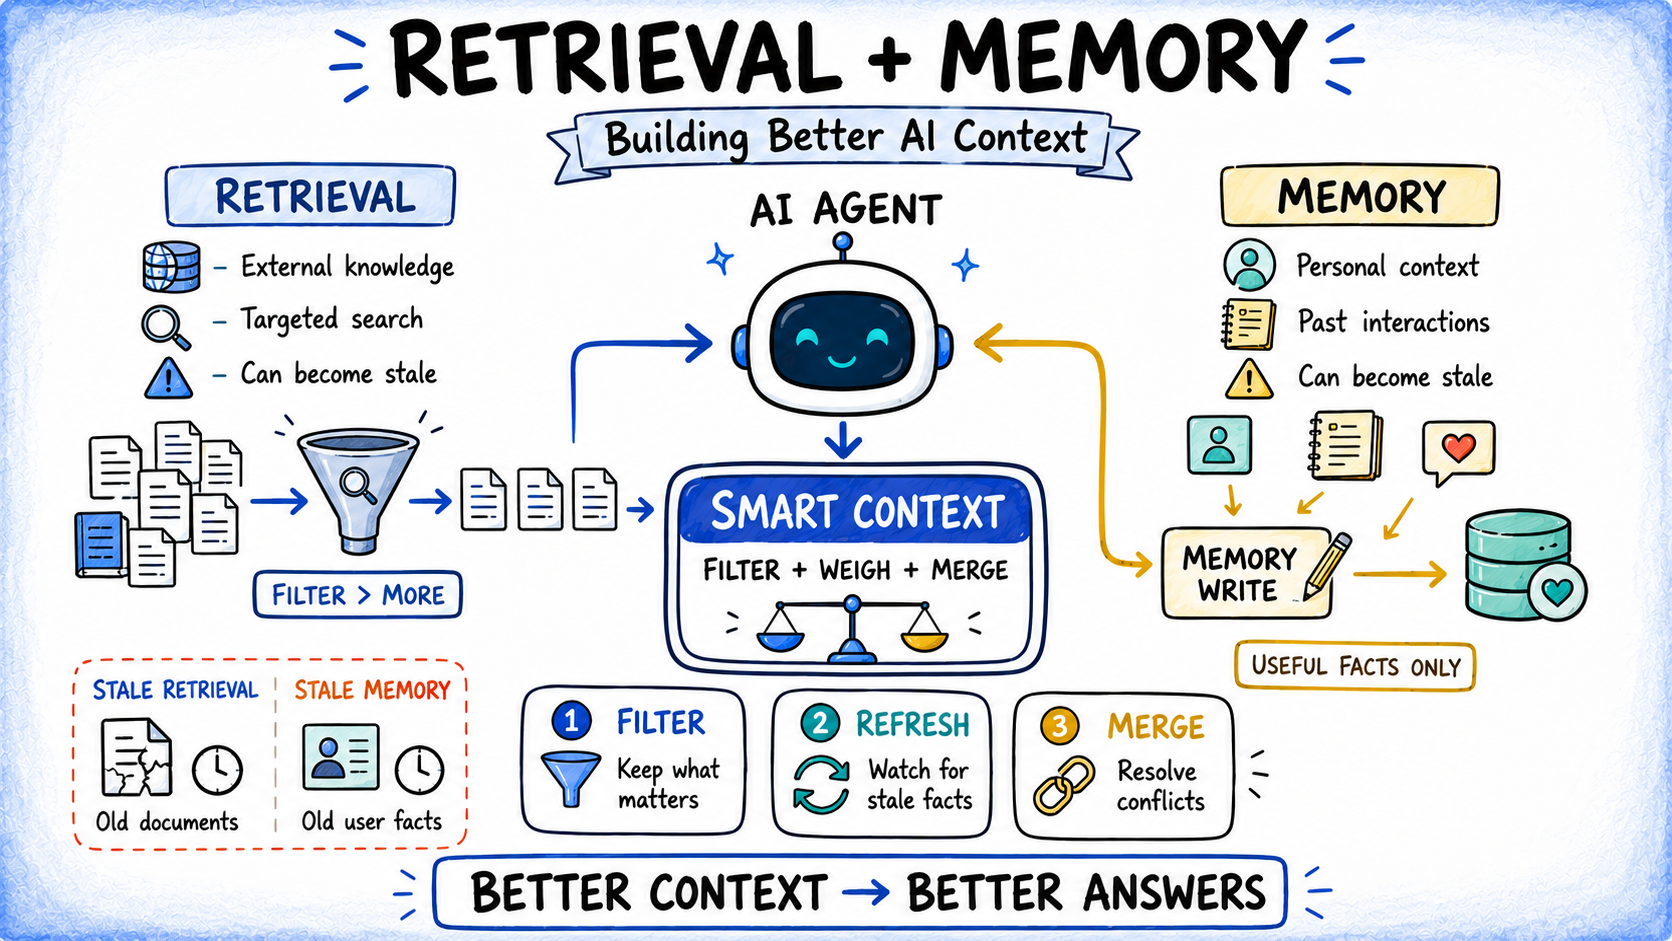
The design work for retrieval and reminiscence comes right down to deciding what belongs in every, how aggressively to prune each, and the way they arrive collectively right into a single immediate with out handing the mannequin tokens it doesn’t want.
Abstract
Retrieval and reminiscence resolve completely different issues in long-running agent techniques. Retrieval brings in exterior data the agent wants in the intervening time, reminiscent of documentation, insurance policies, code, or database data. Reminiscence carries ahead data from earlier interactions, reminiscent of choices, preferences, and user-specific context. The excellence issues as a result of the 2 techniques have completely different scopes, freshness considerations, and failure modes. Retrieval is dependent upon conserving exterior sources updated, whereas reminiscence is dependent upon deciding what’s value storing and when saved data is not legitimate.
The best agent architectures use each. They filter what enters the context, maintain data fairly recent, and merge retrieved data with related reminiscence as an alternative of treating both as an entire report of every little thing the agent must know.
The aim, subsequently, is to offer the agent the context it wants, when it wants it, with out carrying pointless data.