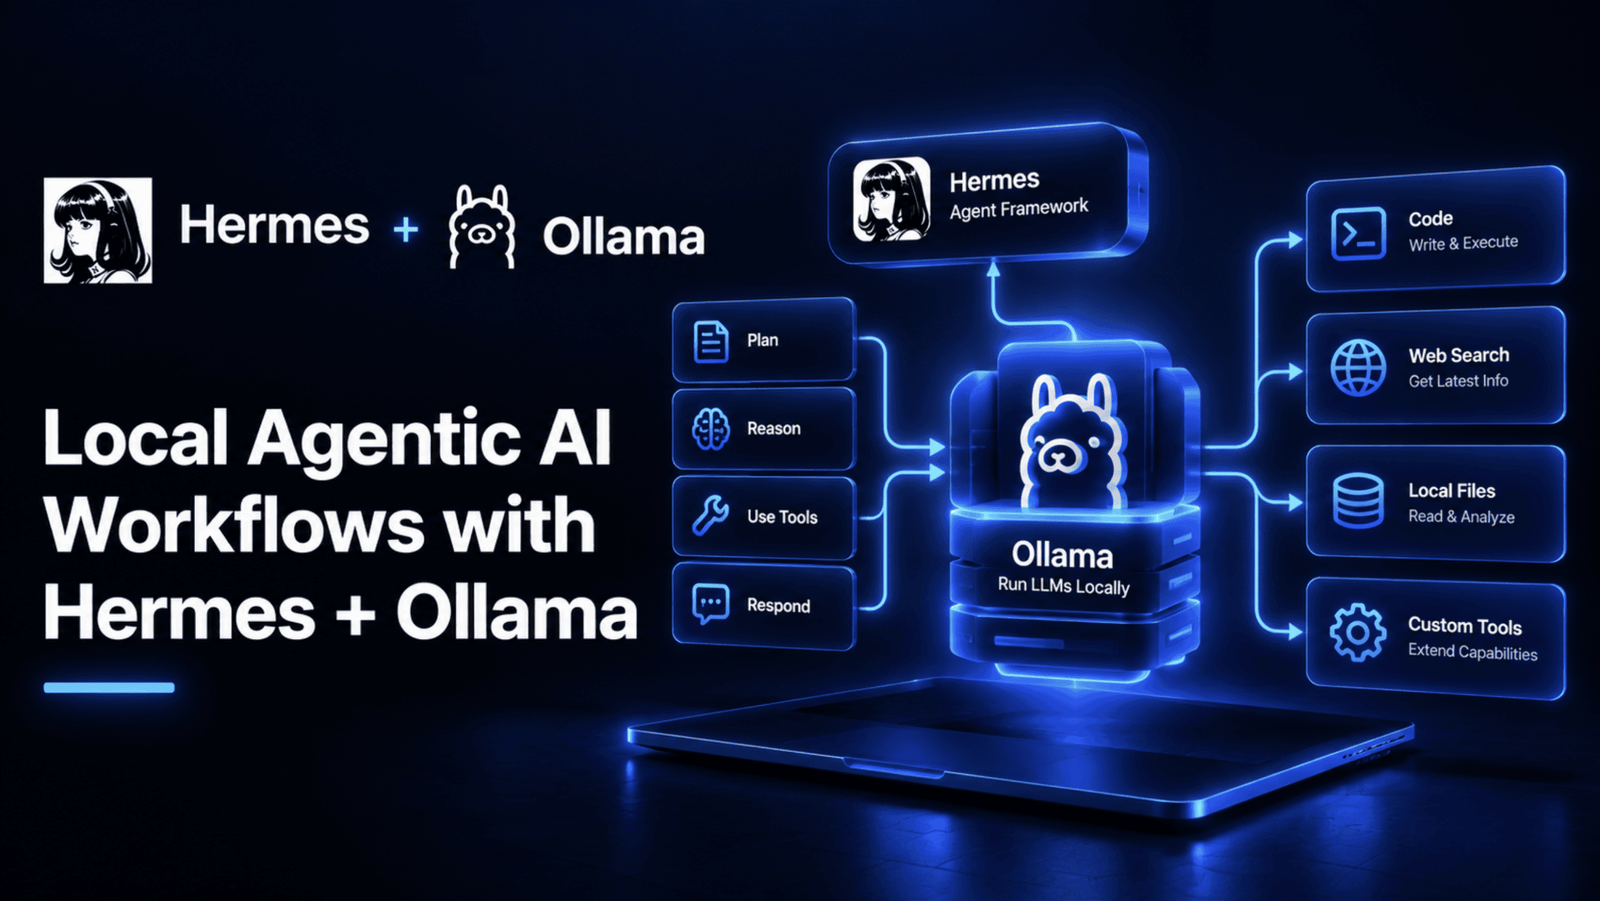
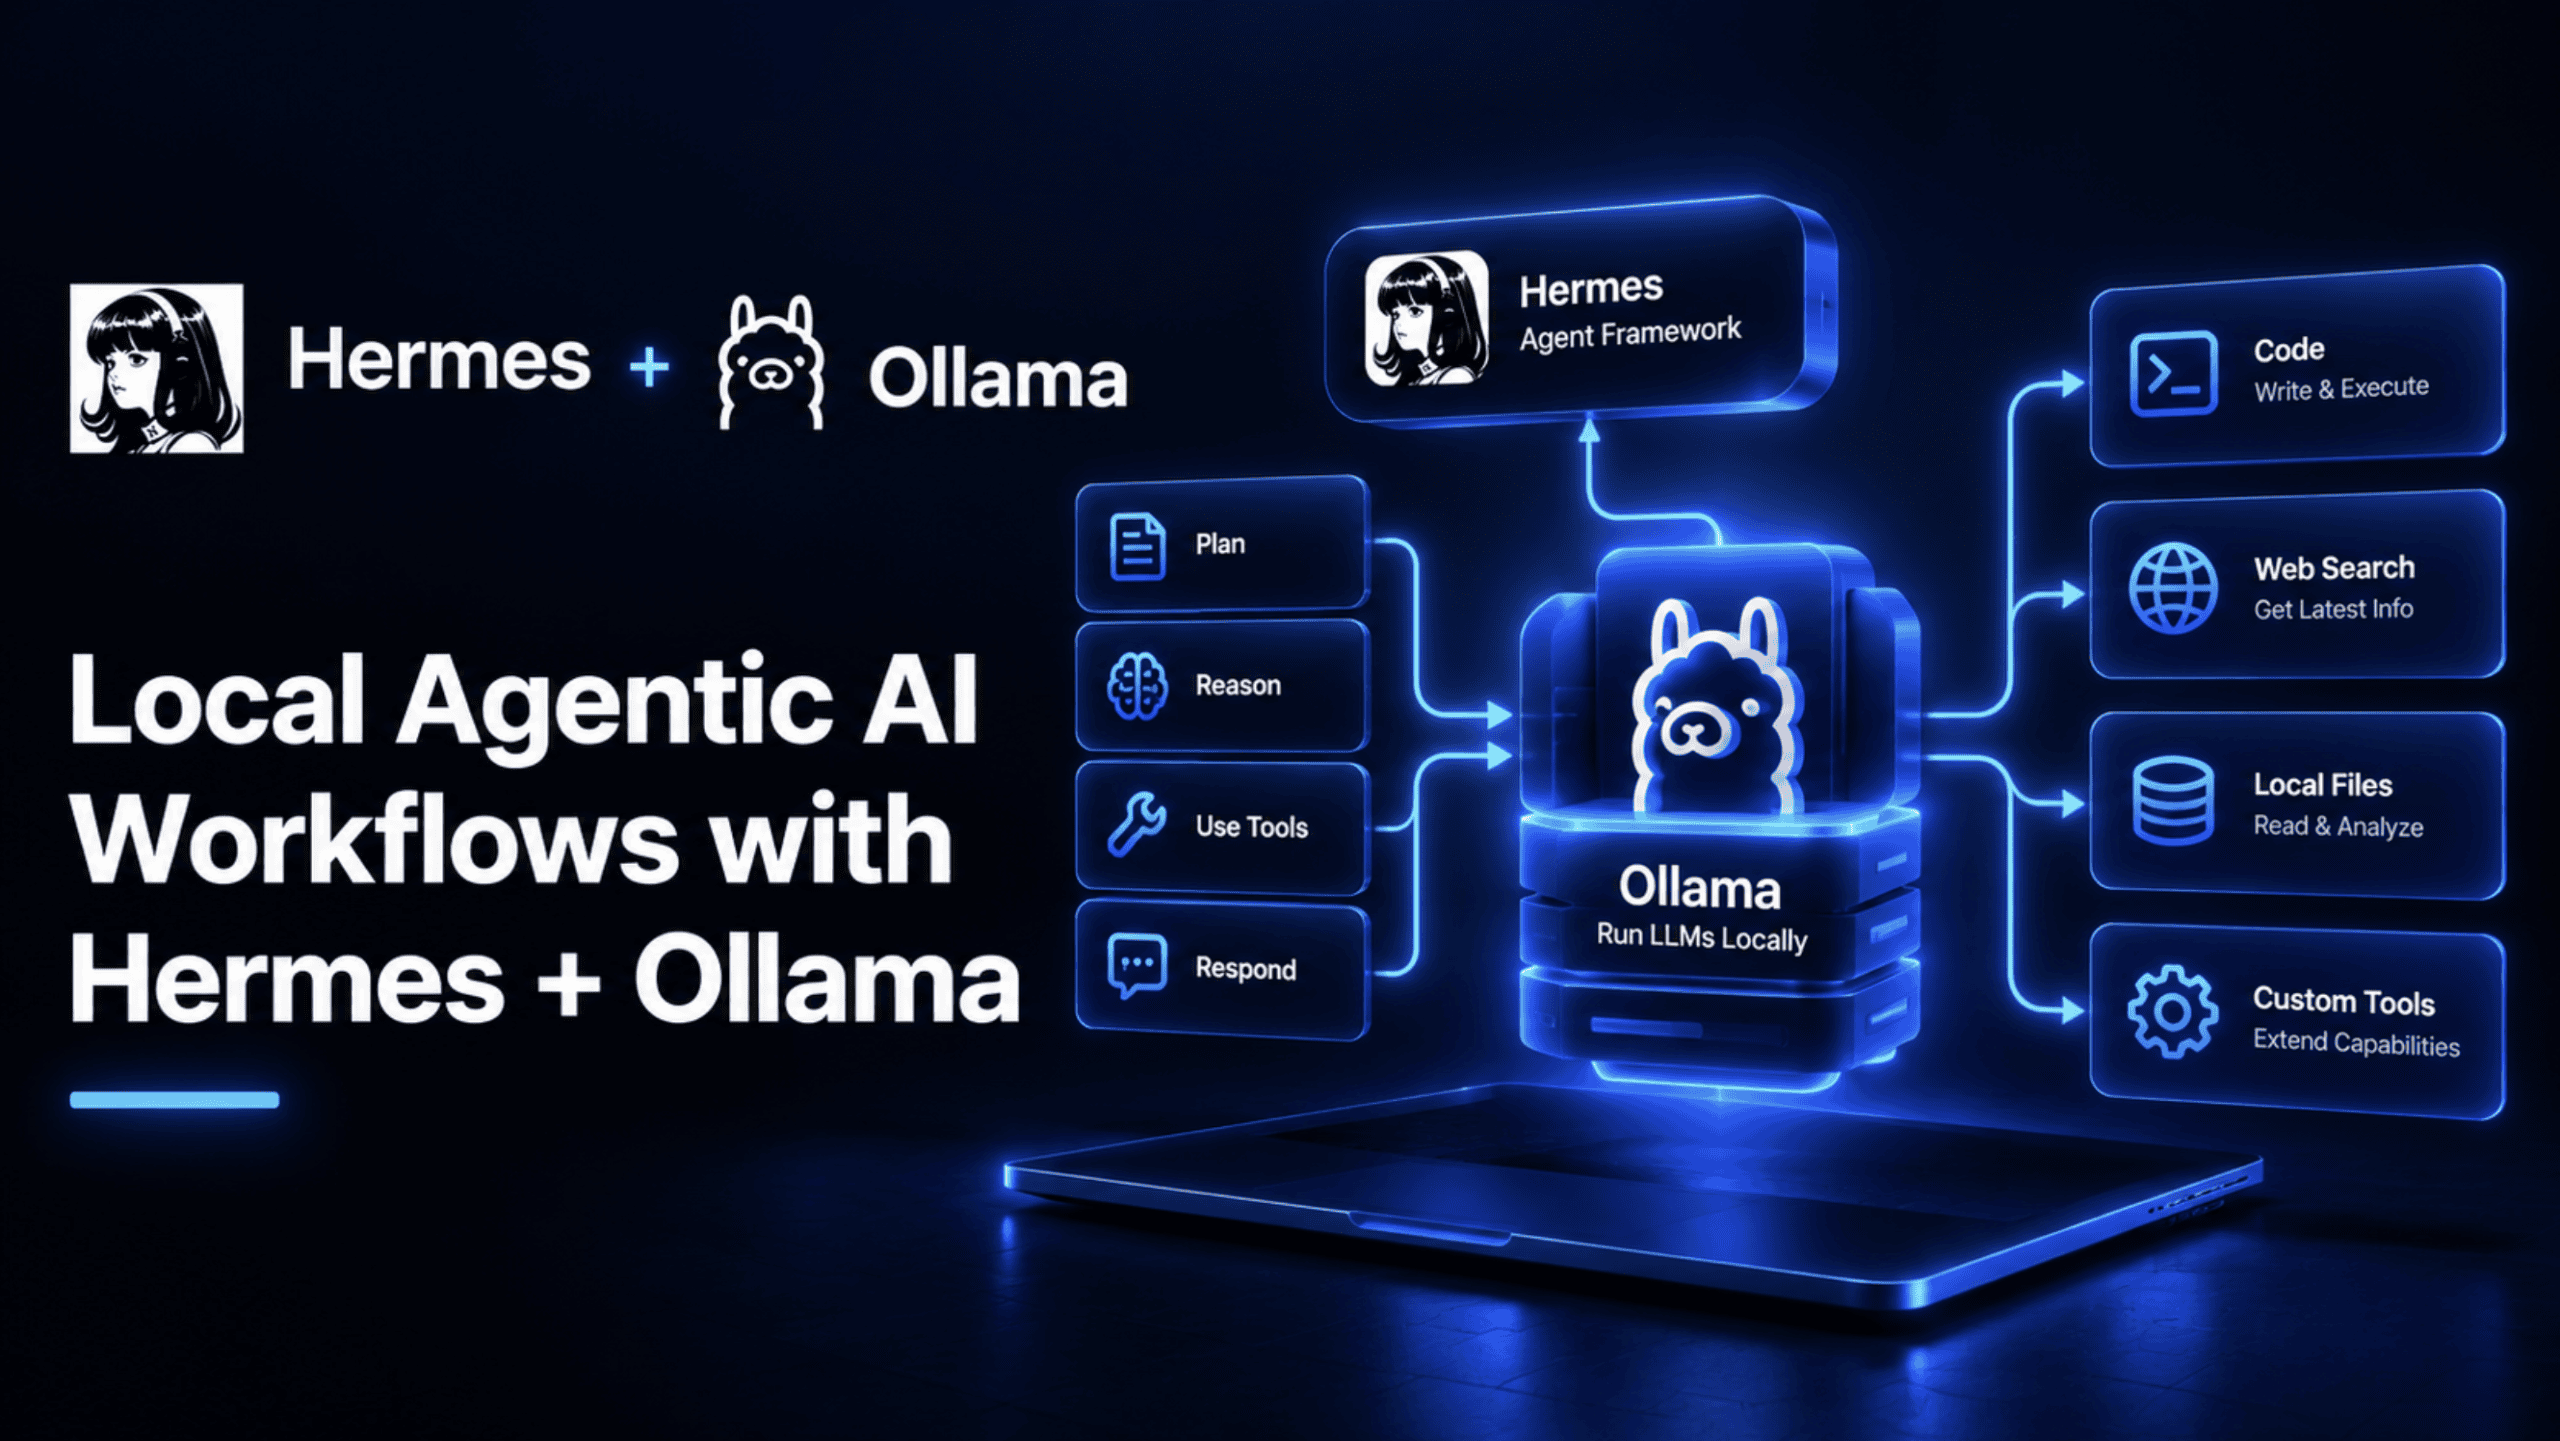
On this article, you’ll discover ways to construct a completely native, zero-cost agentic AI workflow utilizing Hermes Agent and Ollama, in order that your recordsdata, code, and conversations by no means depart your individual {hardware}.
Matters we’ll cowl embody:
- Learn how to set up Ollama, select the fitting native mannequin for agentic work, and confirm that the mannequin is responding appropriately earlier than wiring anything up.
- Learn how to configure Hermes Agent to make use of your native Ollama endpoint, and find out how to optimize context window measurement and mannequin loading for actual agentic duties.
- Learn how to lengthen the setup with a Telegram gateway for distant entry and a cloud fallback for questions the native mannequin can’t deal with properly.
A typical coding session in opposition to a cloud AI API runs someplace between $0.60 and $0.80 relying on the supplier, and a heavier session can climb to $5 to $20, in response to Nous Analysis’s personal price breakdown for agentic work. That provides up quick for a hobbyist, a pupil, or anybody working frequent automation, and it comes with a second price that’s simple to miss: each file, each query, each line of code will get despatched to a 3rd occasion’s servers.
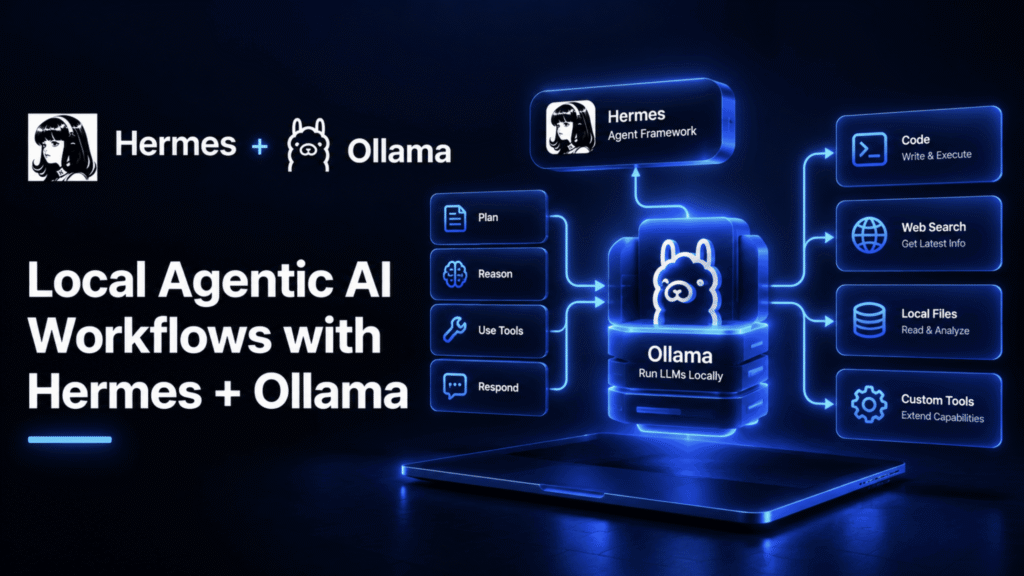
This text builds the choice: a genuinely native, zero-cost agentic AI workflow utilizing Hermes Agent, an open-source AI agent from Nous Analysis, paired with Ollama for native mannequin serving.
What Is Hermes Agent?
Hermes Agent is an open-source AI agent constructed by Nous Analysis, launched beneath the MIT license and at the moment at model 0.21.1 as of this writing. It ships two methods: a local desktop app for macOS, Home windows, and Linux, and a terminal-first CLI you put in straight. What separates it from a fundamental chat interface is real agentic functionality; it edits recordsdata, runs terminal instructions, browses the net, and might delegate work to remoted sub-agents with their very own conversations and instruments.
A couple of options matter particularly for this text. Persistent reminiscence means Hermes learns your tasks over time and might auto-generate reusable abilities from the way it solved previous issues, slightly than ranging from zero each session. Its messaging gateway connects the identical agent and the identical reminiscence to Telegram, Discord, Slack, WhatsApp, and e mail. And its sandboxing system helps 5 totally different isolation backends — native, Docker, SSH, Singularity, and Modal — so instructions it runs shouldn’t have to the touch your host system straight when you would slightly they didn’t.
What Is Ollama?
Ollama is the layer beneath Hermes on this setup: a software that downloads, serves, and manages open-weight language fashions straight by yourself {hardware}, exposing them by means of a neighborhood API that appears and behaves like a regular cloud LLM endpoint. That final element issues greater than it sounds: as a result of Ollama’s API is OpenAI-compatible at /v1/chat/completions, Hermes can speak to a mannequin working totally in your laptop computer utilizing the very same integration path it could use for a cloud supplier like OpenAI or Anthropic — simply pointed at localhost as an alternative of the web.
The division of labor is clear: Ollama’s solely job is working the mannequin and answering requests for it. Hermes’ job is being the precise agent — deciding when to name a software, modifying a file, working a command, searching the net, and decoding what comes again. Neither one replaces the opposite, and this tutorial wants each.
What We’re Constructing
The concrete challenge for this text is a personal, zero-cost native assistant that may set up and reply questions on an actual folder of recordsdata in your machine, search the net when a query genuinely wants present data, and — as soon as the core setup works — keep reachable out of your telephone by way of a Telegram bot when you’re away out of your desk. As a ultimate layer, it should have a cloud fallback configured so genuinely onerous questions nonetheless get answered properly, whereas the opposite 90% of on a regular basis use prices nothing and by no means leaves your machine.
Each part from right here builds one actual piece of that challenge, within the order you’ll truly construct it.
What You Want
{Hardware} necessities scale with the mannequin you propose to run, and it’s price realizing each ends of the vary earlier than selecting.
| Part | Minimal | Really helpful |
|---|---|---|
| RAM | 8 GB (for 3B fashions) | 32+ GB (for 27B+ fashions) |
| Storage | 5 GB free | 30+ GB (for a number of fashions) |
| CPU | 4 cores | 8+ cores |
| GPU | Not required | NVIDIA GPU with 8+ GB VRAM |
CPU-only setups genuinely work; they’re simply slower. A 9B mannequin on a contemporary 8-core CPU runs at roughly 10 tokens per second, whereas a 31B mannequin on CPU drops to about 2 to five tokens per second, which means every response can take 30 to 120 seconds. That’s usable for a background assistant, much less nice for an interactive back-and-forth, which is price factoring into which mannequin you choose.
Set up Ollama and Pull a Mannequin
Set up Ollama with its official set up script:
|
curl –fsSL https://ollama.com/set up.sh | sh |
Verify it’s truly working:
|
ollama —model curl http://localhost:11434/api/tags # Ought to return {“fashions”:[]} |
Anticipated output:
|
$ ollama —model ollama model is 0.33.2
$ curl http://localhost:11434/api/tags {“fashions”:[]} |
The primary command checks that the binary is put in appropriately. The second hits Ollama’s native API straight, and an empty fashions array is the anticipated, right response at this level; it confirms the server is listening — you simply haven’t downloaded a mannequin into it but.
Now pull a mannequin. That is the only most consequential alternative in the entire setup, as a result of not each mannequin can truly act as an agent:
| Mannequin | Measurement on Disk | RAM Wanted | Device Calling | Greatest For |
|---|---|---|---|---|
| gemma4:31b | ~20 GB | 24+ GB | Sure | Highest quality, sturdy software use and reasoning |
| gemma2:27b | ~16 GB | 20+ GB | No | Conversational duties, no software use |
| gemma2:9b | ~5 GB | 8+ GB | No | Quick chat, Q&A, can’t name instruments |
| llama3.2:3b | ~2 GB | 4+ GB | No | Light-weight fast solutions solely |
That “Device Calling” column is the entire ballgame for this challenge. Hermes is an agentic assistant particularly as a result of it could possibly name instruments, edit a file, run a command, search the net, and a mannequin with out tool-call assist can solely chat again at you — it can’t truly take an motion in your behalf, regardless of how properly it writes. For the file-organizing, web-searching assistant this text is constructing, meaning gemma4:31b is the true start line, not the smaller choices.
As soon as it’s downloaded, verify the mannequin itself truly solutions appropriately:
|
curl http://localhost:11434/v1/chat/completions –H “Content material-Sort: utility/json” –d ‘{ “mannequin”: “gemma4:31b”, “messages”: [{“role”: “user”, “content”: “Say hello”}], “max_tokens”: 50 }’ |
Anticipated output:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
{ “id”: “chatcmpl-123”, “object”: “chat.completion”, “created”: 1735689600, “mannequin”: “gemma4:31b”, “selections”: [ { “index”: 0, “message”: { “role”: “assistant”, “content”: “Hello! How can I help you today?” }, “finish_reason”: “stop” } ], “utilization”: { “prompt_tokens”: 10, “completion_tokens”: 9, “total_tokens”: 19 } } |
This sends an actual chat completion request in the identical JSON form an OpenAI-style API expects, which is strictly the purpose: you might be confirming this endpoint behaves like some other LLM API earlier than wiring Hermes as much as it. The response follows Ollama’s documented OpenAI-compatible format precisely; selections[0].message.content material is the precise reply textual content, and this is identical area Hermes itself reads beneath the hood.
Configure Hermes
With Ollama serving a mannequin, level Hermes at it. The guided path is the setup wizard:
When it asks for a supplier, select Customized Endpoint and enter http://localhost:11434/v1 as the bottom URL, depart the API key empty (Ollama doesn’t verify for one), and set the mannequin to gemma4:31b.
The direct path is modifying ~/.hermes/config.yaml your self:
|
mannequin: default: “gemma4:31b” supplier: “customized” base_url: “http://localhost:11434/v1” |
supplier: "customized" is what tells Hermes to deal with this as a generic OpenAI-compatible endpoint slightly than in search of a selected supplier’s authentication scheme. base_url is Ollama’s native handle, and default units which pulled mannequin Hermes truly sends requests to.
Begin Utilizing Hermes
Launch it:
Anticipated output:
|
Hermes Agent v0.21.1 Linked to: gemma4:31b (customized endpoint: http://localhost:11434/v1) Reminiscence: loaded (0 abilities, 0 previous classes)
You: _ |
For the file-organizing challenge from the sooner part, listed below are actual prompts to strive in opposition to an precise challenge folder:
|
You: Checklist all Python recordsdata in this listing and rely the strains of code in every
You: Learn the README.md and summarize what this challenge does
You: Create a Python script that fetches the climate for Ho Chi Minh Metropolis |
Anticipated output (for the primary immediate, shortened):
|
Hermes: I‘ll record the Python recordsdata and rely their strains.
[running: find . –name “*.py” –exec wc –l {} ;]
Discovered 4 Python recordsdata: agent.py 182 strains utils.py 64 strains test_agent.py 103 strains config.py 21 strains
Whole: 370 strains throughout 4 recordsdata. |
Every of those workout routines a special actual functionality — the primary makes use of the terminal and filesystem instruments collectively, the second reads and causes over an actual file’s content material, and the third has the agent write and will optionally run a contemporary script. None of this entails a cloud name; Hermes makes use of the terminal software, file operations, and your native mannequin for all three, which is your entire level of this setup.
Selecting the Proper Mannequin for Your Process
Not each request wants the total 31B mannequin, and working it for a fast factual query wastes time you do not want to spend.
| Process | Really helpful Mannequin | Why |
|---|---|---|
| File edits, code, terminal instructions | gemma4:31b | Solely mannequin right here with dependable software calling |
| Fast Q&A, no software use wanted | gemma2:9b | Quick responses for conversational duties |
| Light-weight chat | llama3.2:3b | Quickest, however very restricted functionality |
Swap fashions mid-session with out restarting something:
Anticipated output:
|
Switched to gemma2:9b. Be aware: this mannequin does not assist software calling, file and terminal actions will be unavailable till you swap again. |
It is a genuinely sensible behavior price constructing early — preserve the massive tool-calling mannequin as your default for the file and internet work this challenge truly wants, and swap all the way down to a lighter mannequin for a fast aspect query, then swap again. Ollama hundreds the lively mannequin into reminiscence on demand and mechanically unloads idle ones, so this switching prices you time on the subsequent load, not disk area sitting unused.
Optimize for Pace
Three actual levers, within the order most individuals really need them.
Enhance Ollama’s context window. Ollama defaults to a 2,048-token context, which is much too small for agentic work — Hermes requires not less than 64,000 tokens to perform correctly with software schemas and file content material in play:
|
cat > /tmp/Modelfile << ‘EOF’ FROM gemma4:31b PARAMETER num_ctx 64000 EOF
ollama create gemma4–64k –f /tmp/Modelfile |
A Modelfile is Ollama’s personal format for customizing a mannequin with out re-downloading it. FROM names the bottom mannequin, and PARAMETER num_ctx 64000 overrides its context window. This produces a brand new named mannequin, gemma4-64k, which you then set because the default in your Hermes config as an alternative of the bottom gemma4:31b.
Hold the mannequin loaded. By default, Ollama unloads a mannequin after 5 minutes of inactivity, which means the subsequent request pays a full reload price:
|
curl http://localhost:11434/api/generate –d ‘{“mannequin”: “gemma4:31b”, “keep_alive”: “24h”}’ |
This single request tells Ollama to carry this mannequin in reminiscence for twenty-four hours no matter idle time, which issues most for the Telegram gateway within the subsequent part — a bot that has to reload a 20 GB mannequin on each incoming message could be unusable.
Use GPU offloading, you probably have one. Ollama mechanically offloads mannequin layers to an obtainable NVIDIA GPU with no configuration wanted. Examine what is definitely occurring with:
This reveals which mannequin is at the moment loaded and the way a lot of it landed on the GPU versus CPU, following Ollama’s documented ps output format. Even a partial offload — roughly 40 layers on a 12 GB GPU for a 31B mannequin, with the remaining on CPU — provides an actual, noticeable speedup over CPU-only.
Elective: Run as a Gateway Bot
With the core agent working, expose it to Telegram so it’s reachable out of your telephone, nonetheless working totally by yourself {hardware}.
Create a bot by means of @BotFather on Telegram and get its token, then add it to ~/.hermes/config.yaml:
|
mannequin: default: “gemma4:31b” supplier: “customized” base_url: “http://localhost:11434/v1”
platforms: telegram: enabled: true token: “YOUR_TELEGRAM_BOT_TOKEN” |
Then begin the gateway as an alternative of the common CLI session:
Anticipated output:
|
Hermes Gateway v0.21.1 Mannequin: gemma4:31b (customized endpoint: http://localhost:11434/v1) Telegram: related as @your_bot_name Listening for messages... |
The platforms.telegram block is additive — it sits alongside the identical mannequin configuration slightly than changing it, which is strictly why the file-organizing assistant you constructed earlier is identical agent now answering you on Telegram: identical reminiscence, identical mannequin, totally different floor.
Elective: Set Up Fallbacks
Native fashions can genuinely wrestle on the toughest questions, and slightly than accepting a foul reply, you may configure a cloud mannequin as a fallback that solely prompts when it’s truly wanted:
|
mannequin: default: “gemma4:31b” supplier: “customized” base_url: “http://localhost:11434/v1”
fallback_providers: – supplier: openrouter mannequin: anthropic/claude–sonnet–4 |
fallback_providers is a listing, evaluated solely when the first mannequin fails or repeatedly produces a malformed response — not on each request. That’s what retains the associated fee mannequin sincere: the massive majority of on a regular basis use stays free and native, and solely the genuinely onerous instances attain a paid API, which is the precise level of constructing a hybrid setup slightly than an all-local or all-cloud one.
Wrapping Up
What you have got working on the finish of this text is an actual, full native workflow: Ollama serving a genuinely tool-capable mannequin by yourself {hardware}, Hermes utilizing that mannequin to learn your recordsdata, run instructions, and search the net with zero API price and 0 knowledge leaving your machine, reachable out of your telephone by means of the Telegram gateway when you’re away out of your desk, with a cloud mannequin ready quietly in reserve for the uncommon query native {hardware} can’t deal with properly.
That’s the precise form of an excellent local-first setup — not all-or-nothing between free-but-limited and capable-but-expensive, however a system the place the free path handles nearly every part and the paid path solely ever will get known as in when it has genuinely earned its price.