On this article, you’ll study what embedding drift is, why it issues for manufacturing massive language fashions, and the right way to implement two sensible methods to detect it.
Subjects we are going to cowl embody:
- The important thing approaches for detecting embedding drift in manufacturing machine studying methods, together with model-based detection, centroid distance, and dimensionality discount mixed with statistical assessments.
- Methods to implement a website classifier and a centroid distance technique utilizing scikit-learn on simulated 384-dimensional embeddings.
- Methods to apply these identical drift detection methods to actual textual content embeddings generated with a SentenceTransformer mannequin by way of Scikit-LLM.
Introduction
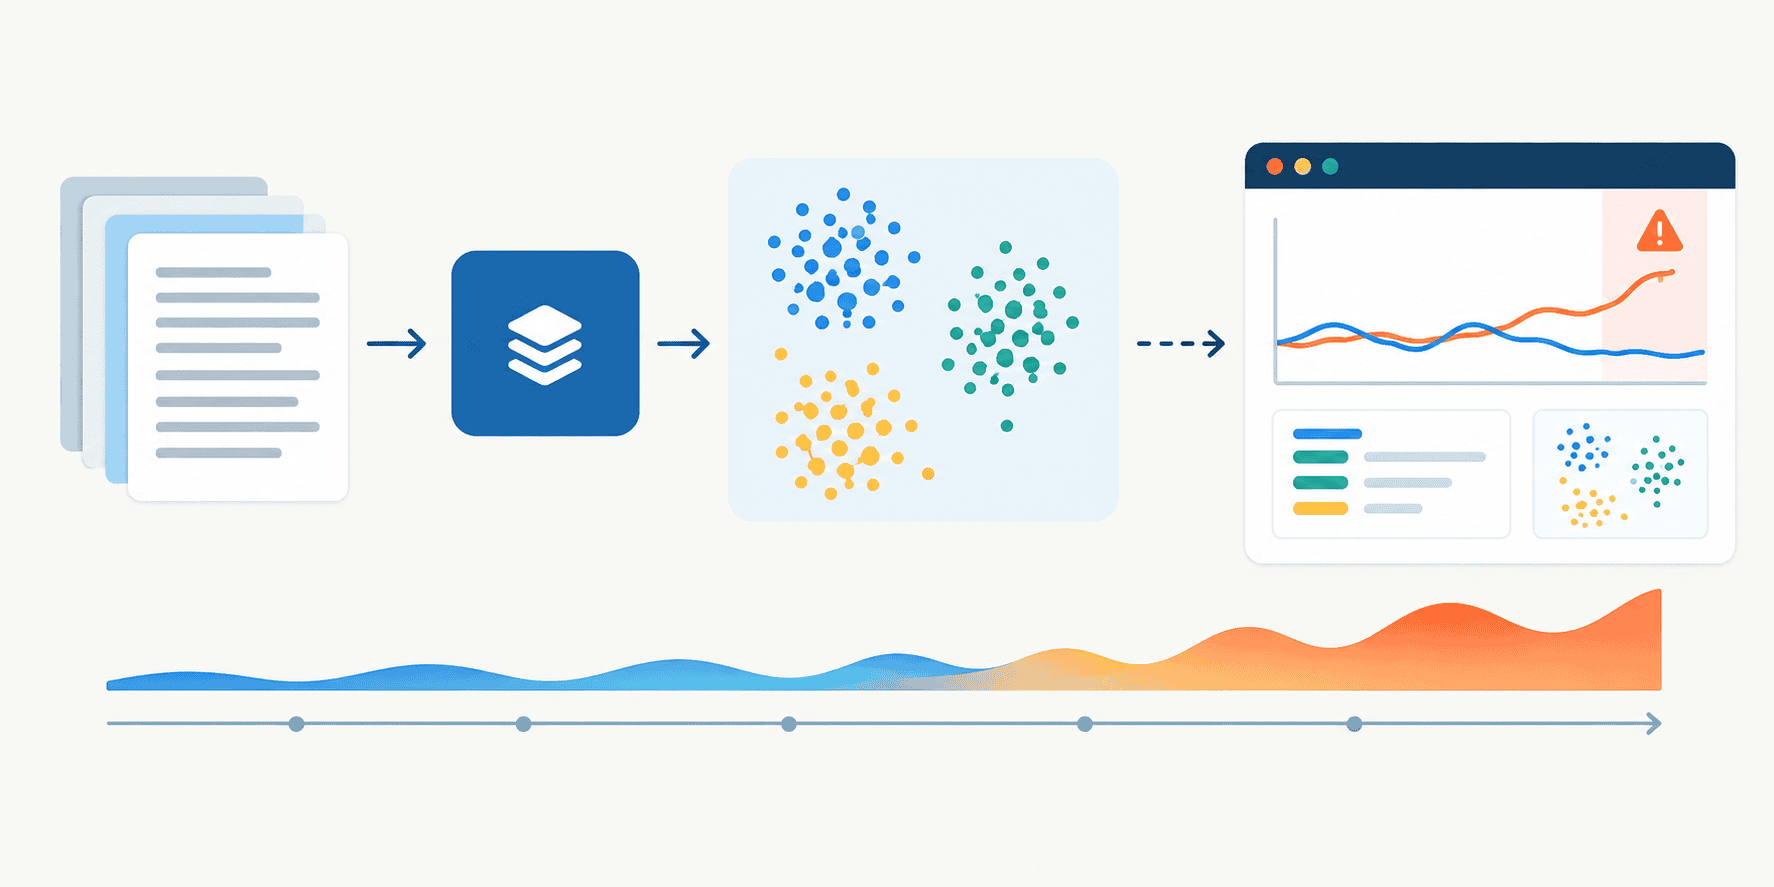
When a big language mannequin (LLM) hits manufacturing, the story is way from over. Person habits inevitably evolves in the actual world, and so does the information consumed by the mannequin, sometimes encoded into numerical textual content representations known as embeddings for its inside processing.
Subsequently, it’s essential to trace so-called embedding drifts to determine when a deployed mannequin wants an replace. Nonetheless, conventional drift detection metrics designed for tabular knowledge typically fail when utilized to high-dimensional embeddings.
This text begins by offering a short define of prime methods for detecting embedding drift, adopted by an illustrative implementation of two of them, each simulation-based and together with the Scikit-LLM library for embedding era.
Methods for Efficient Embedding Drift Detection
Beneath we checklist three key approaches for precisely figuring out embedding drift which were remarkably put into apply in manufacturing LLMs:
- Mannequin-based detection: This consists of coaching a domain-specific classifier, normally a binary classifier that has discovered to tell apart between baseline knowledge and new (drifted) manufacturing knowledge. A mannequin able to simply telling them aside will be capable of sign drifts once they happen.
- Centroid distance: Following classical anomaly detection algorithms, this technique boils right down to calculating the space (typically cosine for embedding knowledge) between the middle of mass of your baseline embedding vectors and that of latest, incoming embedding vectors.
- Combining dimensionality discount and statistical assessments: This technique entails compressing the embeddings to a decrease dimension utilizing UMAP or PCA, after which we apply commonplace drift assessments resembling Kolmogorov-Smirnov.
Thinking about exploring additional how they work? Let’s study the right way to implement the core logic behind two of those methods primarily based on an open-source stack.
Illustrating Drift Detection on Simulated Embeddings
Let’s construct a mathematical basis for 2 of the listed methods utilizing commonplace scikit-learn and simulated embeddings first. We generate an preliminary, random set of embeddings, after which we create one other artificial set — this time containing “manufacturing embeddings” that shift from the unique embeddings’ imply to simulate the existence of knowledge drift.
|
import numpy as np
# Simulating 384-dimensional embeddings (e.g. commonplace sentence-transformers output) n_samples = 500 n_features = 384
# 1. Referencing Embeddings (Baseline / Coaching Knowledge) # Think about that is the information your LLM/Vector DB was initially populated with np.random.seed(42) X_reference = np.random.regular(loc=0.0, scale=1.0, measurement=(n_samples, n_features))
# 2. Manufacturing Embeddings (New Knowledge) # The unique imply is shifted to loc=0.3 to simulate knowledge drift (e.g. new matter rising) X_production = np.random.regular(loc=0.3, scale=1.0, measurement=(n_samples, n_features)) |
Subsequent, we practice a area classifier primarily based on random forests to separate baseline knowledge (labeled 0) from new, manufacturing knowledge (labeled 1). If the accuracy metric — as an illustration, ROC-AUC — indicators a excessive worth, e.g. above 0.65, the classifier will set off a drift alert.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 |
from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import train_test_split from sklearn.metrics import roc_auc_rating
# 1. Assigning labels: 0 for reference, baseline embeddings; 1 for manufacturing embeddings y_reference = np.zeros(n_samples) y_production = np.ones(n_samples)
# 2. Combining right into a single dataset X_combined = np.vstack((X_reference, X_production)) y_combined = np.hstack((y_reference, y_production))
# 3. Randomly splitting into practice and check units for the drift detector X_train, X_test, y_train, y_test = train_test_split( X_combined, y_combined, test_size=0.3, random_state=42 )
# 4. Coaching a light-weight Random Forest classifier drift_classifier = RandomForestClassifier(n_estimators=50, max_depth=5, random_state=42) drift_classifier.match(X_train, y_train)
# 5. Evaluating the classifier utilizing ROC-AUC y_pred_proba = drift_classifier.predict_proba(X_test)[:, 1] roc_auc = roc_auc_score(y_test, y_pred_proba)
print(f“Area Classifier ROC-AUC Rating: {roc_auc:.3f}”)
# 6. Alerting Logic # If the metric rating is round 0.5 it means the mannequin cannot inform the datasets aside (no drift detected). # In the meantime, a rating nearer to 1.0 means they’re simply distinguishable (excessive drift). if roc_auc > 0.65: print(“ALERT: Vital embedding drift detected! Set off retraining/overview pipeline.”) else: print(“System secure: Distributions are sufficiently comparable.”) |
Output:
|
Area Classifier ROC–AUC Rating: 0.970 ALERT: Vital embedding drift detected! Set off retraining/overview pipeline. |
Alternatively, we are able to resort to the centroid calculation approach, often known as the “heart of mass” technique, measuring the space between two centroids: one stemming from the baseline embeddings and one related to the brand new, manufacturing embeddings. This technique is computationally cheaper than the classifier technique, but it surely incurs a lack of nuance (useful data): in spite of everything, aggregating high-dimensional vectors right into a single central level throws away advanced distribution shapes, masking necessary patterns like multi-modal shifts or structural adjustments within the knowledge.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
from sklearn.metrics.pairwise import cosine_distances
# 1. Calculating the centroid (imply vector) for each batches # axis=0 calculates the imply throughout all samples, leading to a single 384-d vector centroid_ref = np.imply(X_reference, axis=0).reshape(1, –1) centroid_prod = np.imply(X_production, axis=0).reshape(1, –1)
# 2. Calculating the space (1 – Cosine Similarity) between the 2 centroids # A distance of 0 means equivalent path; greater means they’re drifting aside distance = cosine_distances(centroid_ref, centroid_prod)[0][0]
print(f“Centroid Cosine Distance: {distance:.4f}”)
# 3. Alerting Logic # Figuring out the precise threshold requires tuning in accordance along with your particular mannequin and baseline variance threshold = 0.05 if distance > threshold: print(“ALERT: Centroid distance exceeded threshold! System drifting.”) else: print(“System secure: Centroids are aligned.”) |
Output:
|
Centroid Cosine Distance: 0.9811 ALERT: Centroid distance exceeded threshold! System drifting. |
Little question the cosine distance worth appears to be like a bit exaggerated, resulting from a mix of the orthogonal nature of the space metric used and the truth that the baseline knowledge had been generated randomly. A extra life like dataset would usually yield excessive distances within the presence of topic-driven knowledge drifts, however not so excessive within the majority of circumstances. Let’s discover out with a ultimate instance that makes use of Scikit-LLM to generate embeddings from actual textual content.
Drift Detection on Generated Embeddings with Scikit-LLM
The final code instance makes use of Scikit-LLM as a wrapper for a Groq LLM specialised in embedding era. It has been run on Google Colab, with an API key obtained from Groq (a free LLM repository) and saved within the “My Secrets and techniques” part of the left-hand aspect menu.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 |
from sentence_transformers import SentenceTransformer from google.colab import userdata from skllm.config import SKLLMConfig
# Securely extract the Groq API Key you’ll have beforehand saved in Colab secrets and techniques groq_api_key = userdata.get(‘GROQ_API_KEY’)
# Redirecting scikit-LLM to Groq utilizing API compatibility: SKLLMConfig.set_openai_key(groq_api_key) SKLLMConfig.set_gpt_url(“https://api.groq.com/openai/v1/”)
# Since Groq doesn’t have an embeddings API, we are able to use a free and really light-weight native mannequin vectorizer = SentenceTransformer(‘all-MiniLM-L6-v2’)
# Baseline uncooked texts and manufacturing texts, clearly with a drastic matter shift texts_reference = [ “How do I reset my password?”, “Where is the billing menu?” ] * 100 # We multiply to simulate a bigger dataset
texts_production = [ “The new cryptocurrency system is failing”, “How to mint an NFT on the platform?” ] * 100
# Changing textual content to embeddings X_reference = vectorizer.encode(texts_reference) X_production = vectorizer.encode(texts_production)
# Implementing Embedding Drift Detection Logic # Assign labels: 0 for reference, 1 for manufacturing y_reference = np.zeros(len(X_reference)) y_production = np.ones(len(X_production))
# Combining datasets X_combined = np.vstack((X_reference, X_production)) y_combined = np.hstack((y_reference, y_production))
# Coaching the area classifier X_train, X_test, y_train, y_test = train_test_split( X_combined, y_combined, test_size=0.3, random_state=42 ) clf = RandomForestClassifier(n_estimators=50, max_depth=5).match(X_train, y_train)
# Calculating drift utilizing ROC-AUC roc_auc = roc_auc_score(y_test, clf.predict_proba(X_test)[:, 1])
print(f“ROC-AUC Rating: {roc_auc:.3f}”) if roc_auc > 0.65: print(“DRIFT DETECTED! Person queries have modified matter.”) else: print(“System secure: Embeddings are constant.”) |
The method is just like what we noticed earlier. The principle distinction lies within the knowledge used, which at the moment are embeddings generated from actual textual content examples. As a result of deliberately drastic matter distinction between the 2 datasets, the classifier can completely distinguish between baseline and manufacturing embeddings:
|
ROC–AUC Rating: 1.000 DRIFT DETECTED! Person queries have modified matter. |
Let’s additionally strive the centroid technique yet one more time:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 |
from sklearn.metrics.pairwise import cosine_distances import numpy as np
# Centroid Distance for SentenceTransformer embeddings
# Calculate centroids centroid_ref_st = np.imply(X_reference, axis=0).reshape(1, –1) centroid_prod_st = np.imply(X_production, axis=0).reshape(1, –1)
# Calculate cosine distance distance_st = cosine_distances(centroid_ref_st, centroid_prod_st)[0][0]
print(f“Centroid Cosine Distance (SentenceTransformer Embeddings): {distance_st:.4f}”)
# Alerting Logic threshold_st = 0.05 # Regulate threshold as wanted if distance_st > threshold_st: print(“ALERT: Centroid distance exceeded threshold! System drifting (SentenceTransformer Embeddings).”) else: print(“System secure: Centroids are aligned (SentenceTransformer Embeddings).”) |
Output:
|
Centroid Cosine Distance (SentenceTransformer Embeddings): 0.8719 ALERT: Centroid distance exceeded threshold! System drifting (SentenceTransformer Embeddings). |
As we are able to see, monetary/crypto subjects and fundamental IT help will be far aside within the embedding house managed by our chosen mannequin, all-MiniLM-L6-v2, which nonetheless yields a excessive cosine distance — though not almost as excessive as within the purely random knowledge state of affairs.
Wrapping Up
This text launched some frequent methods utilized in manufacturing machine studying methods to watch and detect drifts in knowledge represented as vector embeddings. Two of those methods, specifically model-based detection and the centroid distance technique, have been illustrated by means of code examples, aided by Scikit-LLM for embedding era.