At any time when a single vendor captures 80 p.c of a extremely profitable market, historical past tells us two issues are about to occur. First, the dominant participant will start to behave as if their moat is impenetrable, usually prioritizing lock-in and margin over buyer flexibility. Second, a hyper-focused challenger will quietly chip away on the basis of that dominance till the market immediately realizes a viable various has arrived. We noticed it when AMD’s Opteron blindsided Intel within the knowledge heart twenty years in the past, and we’re watching it occur once more proper now within the synthetic intelligence accelerator house.
For the final three years, Nvidia has been the undisputed king of AI. Its {hardware} was the usual, and its CUDA software program ecosystem was the moat that stored clients from leaving. However within the know-how sector, software program moats ultimately evaporate when {hardware} efficiency deltas turn into too giant to disregard.
This week, the MLPerf Inference 6.1 outcomes had been launched, they usually symbolize a seismic shift within the AI panorama. AMD didn’t simply present as much as compete; they confirmed as much as win. And for IT consumers and knowledge heart architects their 2027 budgets, the belief is setting in: Nvidia is now not the one protected wager, and in lots of essential workloads, they aren’t even the quickest one.
The MLPerf 6.1 Breakthrough: Beating Blackwell
To grasp why it is a turning level, you must have a look at the uncooked knowledge. The MLPerf benchmark is the trade’s gold normal for evaluating AI efficiency, reducing via advertising fluff to ship verified, repeatable outcomes. As detailed of their latest breakdown of the MLPerf Inference 6.1 submission, AMD delivered a masterclass in silicon execution.
Probably the most surprising revelation from the benchmark was the head-to-head efficiency in opposition to Nvidia’s extremely touted Blackwell structure. AMD’s Intuition MI355X GPU truly led Nvidia’s B200 and B300 in GPT-OSS-120B outcomes on the 8-GPU scale. Much more impressively, on the 72-GPU rack scale, the MI355X outperformed Nvidia’s flagship GB200 platform. We’re now not speaking about AMD as a “funds various.” We’re speaking about AMD taking absolutely the efficiency crown from Nvidia’s latest, costliest silicon.
But it surely’s not nearly peak {hardware}; it’s about software program maturation. AMD’s submission proved that their ROCm software program stack is lastly hitting its stride. On the very same MI355X {hardware} from earlier testing rounds, continued ROCm optimizations delivered a 38 p.c improve in server throughput for GPT-OSS-120B and decreased latency by a staggering 70 p.c on the Wan-2.2 text-to-video mannequin.
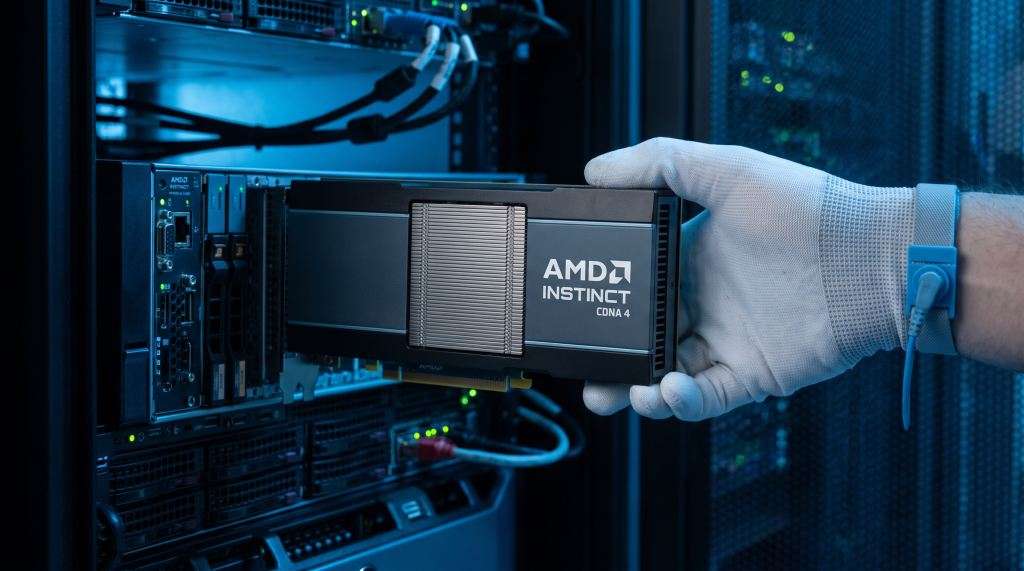
Moreover, AMD launched the MI350P, a dual-slot PCIe card constructed on the CDNA 4 structure, designed to fit effortlessly into present knowledge heart infrastructure. In its very first MLPerf exhibiting, the MI350P outperformed Nvidia’s RTX PRO 6000 and H200 NVL. Add in accomplice Crusoe’s huge 512-GPU submission hitting an unprecedented 5.75 million tokens per second, and you’ve got a {hardware} ecosystem that’s scaling flawlessly from single-node edge deployments to huge cloud clusters.
The Energy of Singular Focus
Why is AMD pulling forward? The reply lies within the firms’ respective company methods and CEO Lisa Su’s ruthless execution.
Nvidia, beneath Jensen Huang, has been making an attempt to construct the whole world. They’re constructing CPUs, networking gear, full rack-scale methods, and a proprietary software program ecosystem. They wish to be the IBM of the AI period—controlling the whole stack high to backside. Whereas that drives huge margins within the quick time period, it additionally creates a large floor space to defend. It alienates OEM companions who really feel relegated to mere resellers, and it frustrates cloud suppliers who hate being locked right into a single provider’s margin construction.
AMD, however, has maintained a singular, laser-like deal with one factor: delivering the highest-performing compute engines on the planet. They aren’t making an attempt to lock you right into a proprietary networking cloth or pressure you to purchase their rack designs. They’re constructing parts – extremely highly effective ones with huge reminiscence footprints just like the MI355X’s 288GB of HBM3E – and handing them over to an open ecosystem.
This tight deal with uncooked efficiency is why they’re profitable. In AI inference, reminiscence bandwidth and capability are the first bottlenecks. By over-indexing on HBM3E capability whereas Nvidia skimped to guard margins and phase their product stack, AMD gave builders the {hardware} they really wanted for large fashions like Llama 3 and GPT-OSS. Uncooked efficiency ultimately forces software program to adapt, and we’re seeing the open-source group rally round AMD exactly as a result of the {hardware} is simply too good to disregard.
The Path Ahead for AMD
In fact, profitable a benchmark isn’t the identical as profitable the market. Nvidia nonetheless holds roughly 80 p.c of the AI accelerator income share as of late 2026. For AMD to totally profit competitively from these MLPerf outcomes, they must execute flawlessly on three fronts.
First, they need to speed up the democratization of their software program stack. ROCm has improved vastly, however AMD must push the trade totally towards hardware-agnostic frameworks like Triton and the UXL Basis. The objective shouldn’t be to make ROCm the brand new CUDA; the objective ought to be to make CUDA irrelevant. If a developer can write a mannequin as soon as in an open framework and have it run optimally on AMD, Nvidia’s moat vanishes.
Second, AMD must aggressively assist their OEM and hyperscaler companions. Nvidia’s full-system strategy (just like the GB200 NVL72) competes immediately with server makers like Dell, HPE, and Lenovo. AMD should lean into this friction, offering these OEMs with the reference architectures and engineering assist they should construct methods that definitively outclass Nvidia’s proprietary racks. AMD must be the last word accomplice, not a competitor to its personal provide chain.
Lastly, AMD should guarantee aggressive and unyielding provide chain parity. The most important problem to adopting AMD over the past two years hasn’t all the time been efficiency; it’s been availability. AMD should safe sufficient superior packaging and HBM quantity to ensure that when a cloud supplier needs 100,000 GPUs, AMD can ship them quicker than Nvidia can.
Predicting the Flip: When Will AMD Go Nvidia?
If AMD executes on this path, the market flip isn’t a matter of if, however when. Know-how markets hardly ever shift in a single day, however after they do, the momentum is exponential. Right here is the possible sequence of occasions main as much as AMD passing Nvidia in knowledge heart AI accelerator market share.
Part 1: {Hardware} Superiority and Proof of Idea (2026). We’re on this part proper now. The MLPerf 6.1 outcomes show that AMD has the superior silicon and that the software program is able to extracting that efficiency. The early adopters and extremely technical hyperscalers are proving that AMD clusters might be deployed at scale with out regression.
Part 2: The TCO Awakening (2027). Because the AI market shifts from the coaching part (which is extremely compute-intensive and closely reliant on historic CUDA codebases) to the inference part (which is extremely memory-bound and cost-sensitive), Whole Price of Possession will turn into the first driver. With AMD providing considerably extra reminiscence per GPU and working at a lower cost level, cloud suppliers will start closely incentivizing clients to make use of AMD cases. We’ll see main cloud suppliers shift their default AI inference choices from Nvidia to AMD to protect their very own margins.
Part 3: The Ecosystem Tipping Level (2028). By 2028, the open-source software program layer might be fully abstracted from the {hardware}. A brand new technology of AI builders will enter the workforce having by no means written a line of CUDA, relying totally on high-level frameworks. Nvidia’s software program moat might be totally neutralized. Throughout this part, enterprise consumers who traditionally purchased Nvidia for “security” will notice they’re overpaying for underperforming {hardware}. The OEM channel will shift closely towards AMD to regain management of their very own server designs.
Part 4: The Flippening (2029 – 2030). Someday round late 2029 or early 2030, the traces will cross. Nvidia will nonetheless have a large put in base of legacy coaching clusters, however the net-new deployments for inference, enterprise AI, and agentic workflows will closely favor AMD. AMD will surpass Nvidia in annual AI accelerator unit shipments, and shortly thereafter, in income share. Nvidia might be pressured to compete on value, collapsing their astronomical margins and completely altering the dynamics of the semiconductor trade.
Wrapping Up
Nvidia has loved probably the most outstanding runs within the historical past of the know-how trade, however the MLPerf 6.1 outcomes are the writing on the wall. You can not preserve a proprietary monopoly indefinitely when a competitor is delivering higher {hardware}, scaling it effectively, and empowering an open-source software program motion to tear down your moat.
AMD’s singular deal with efficiency and execution has efficiently neutralized Nvidia’s Blackwell structure earlier than it may even set up true dominance. The transition received’t occur tomorrow, however the sequence of occasions has already been set in movement. {Hardware} parity has been achieved. The software program hole is closing quickly. The TCO benefits are evident. For enterprise IT consumers and cloud architects, the message from MLPerf 6.1 is evident: the period of the Nvidia monopoly is ending, and the period of the open, AMD-powered AI knowledge heart has arrived. Plan your budgets accordingly.

As President and Principal Analyst of the Enderle Group, Rob gives regional and world firms with steerage in the best way to create credible dialogue with the market, goal buyer wants, create new enterprise alternatives, anticipate know-how modifications, choose distributors and merchandise, and follow zero greenback advertising. For over 20 years Rob has labored for and with firms like Microsoft, HP, IBM, Dell, Toshiba, Gateway, Sony, USAA, Texas Devices, AMD, Intel, Credit score Suisse First Boston, ROLM, and Siemens.