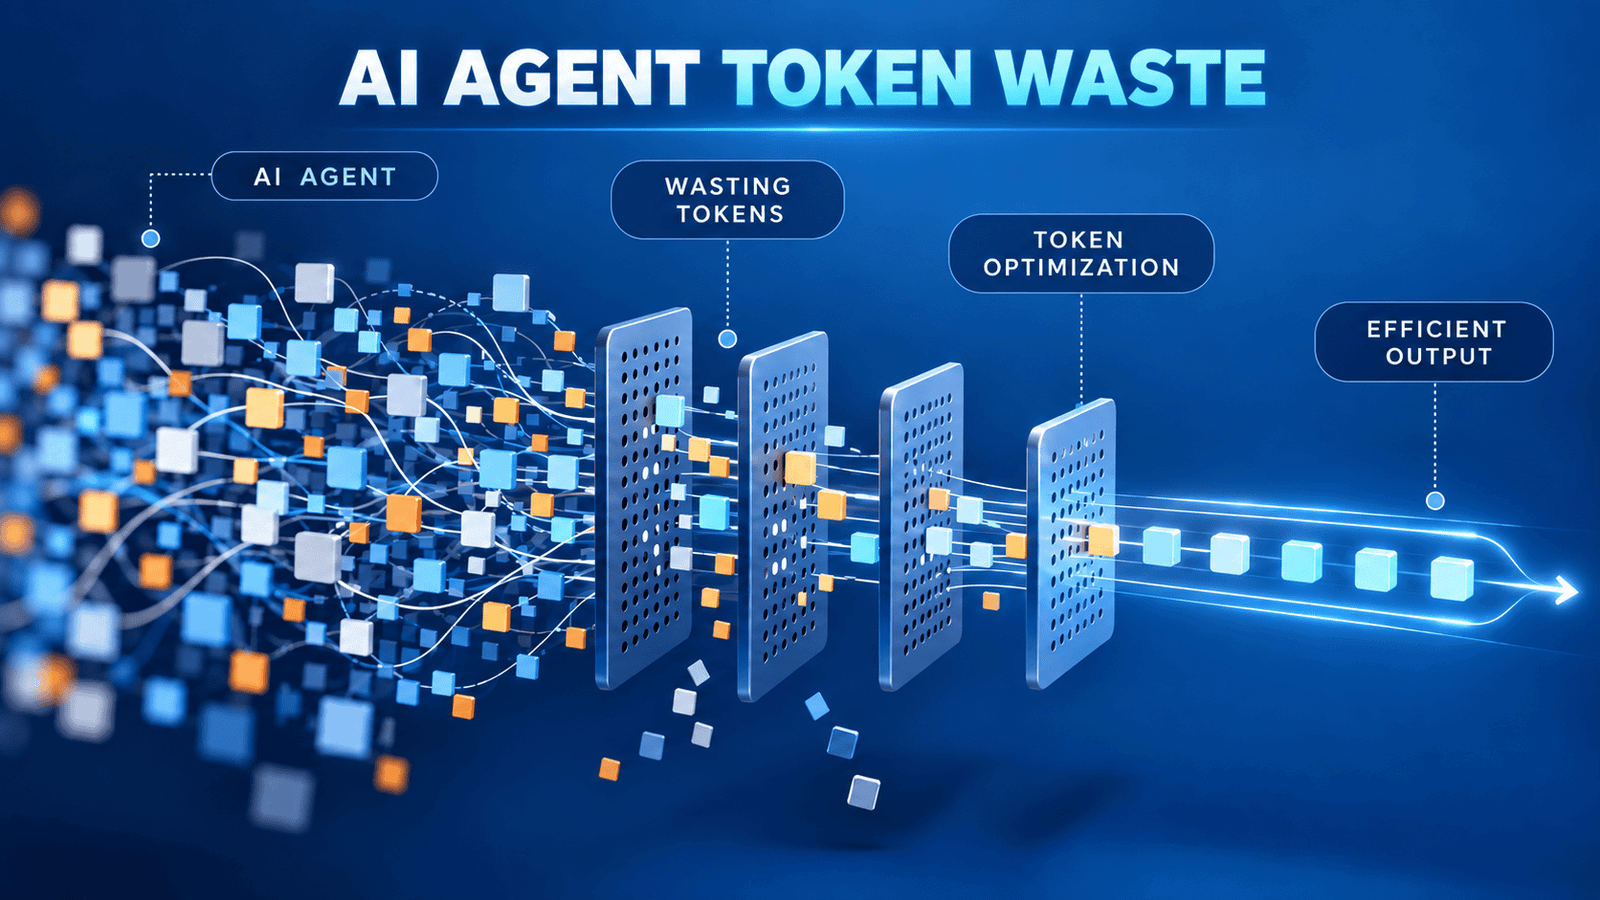
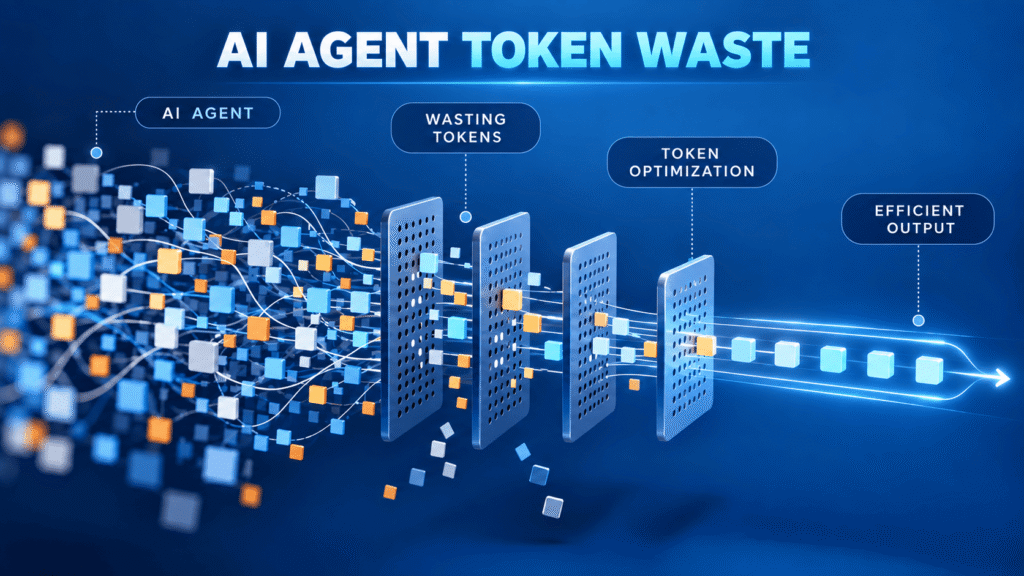
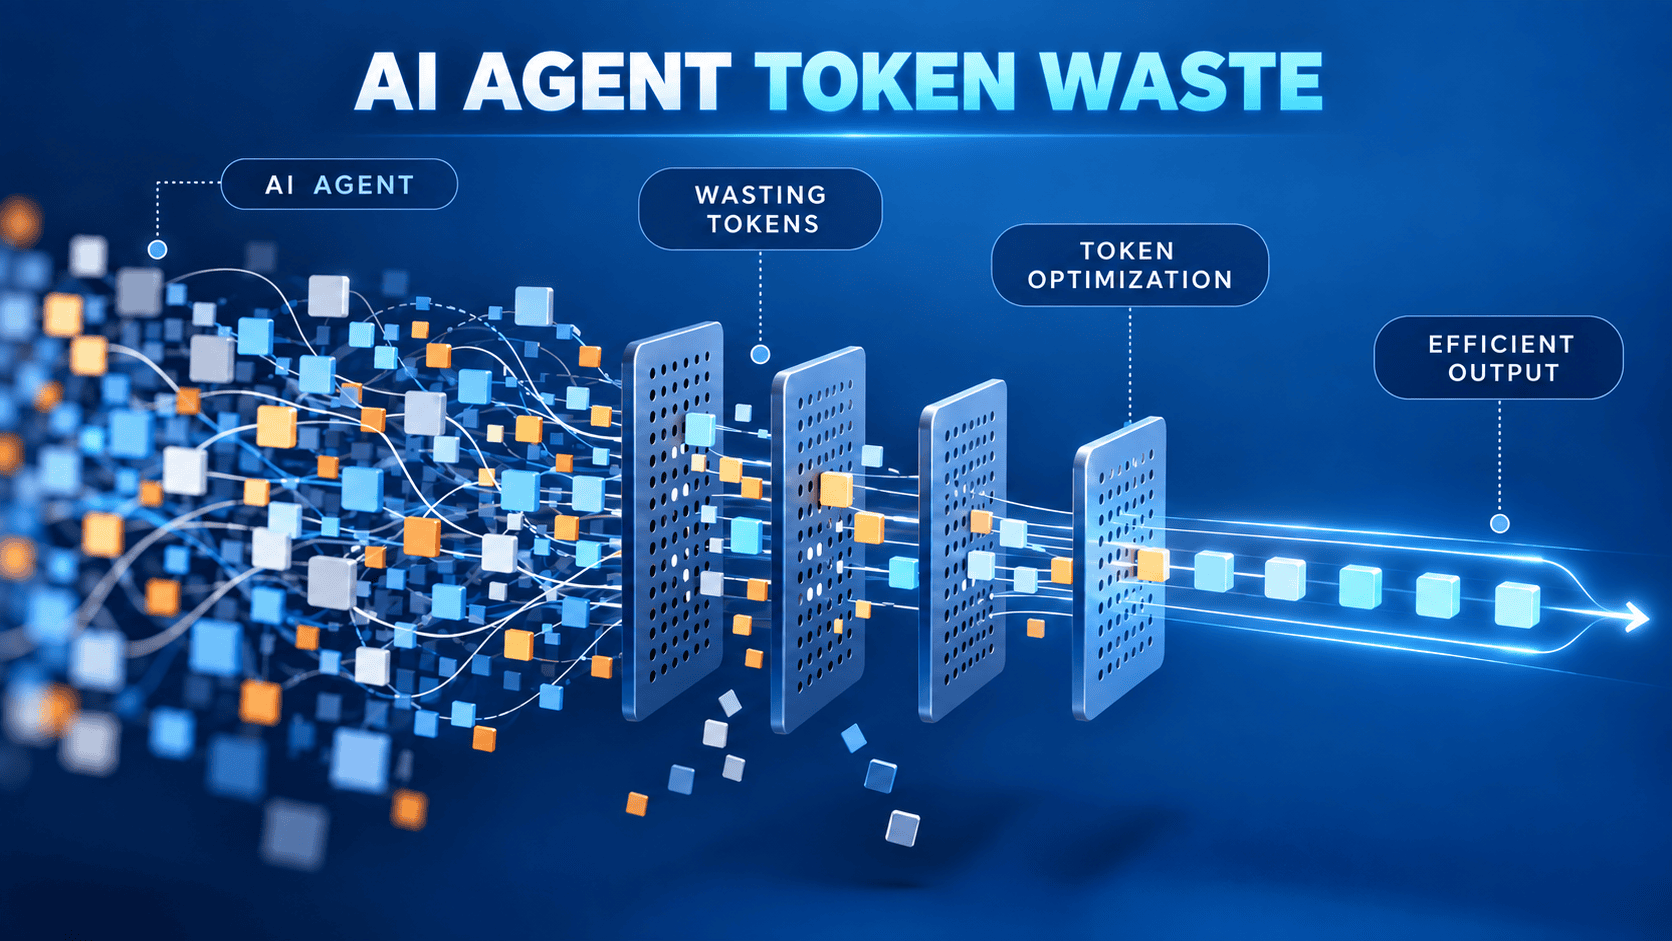
On this article, you’ll be taught seven frequent token-waste patterns in manufacturing AI agent techniques, and the architectural fixes that tackle each.
Matters we are going to cowl embrace:
- How treating the context window as a system of report inflates prices and latency, and the best way to repair it with sliding home windows and semantic summarization.
- How uncompressed software outcomes, static schema bloat, and naive retrieval patterns silently drain your token funds.
- How you can use circuit breakers, immediate prefixing, cascaded routing, and constrained output codecs to construct cost-stable agent architectures.
Introduction
Prototyping an agent over a weekend is one drawback. Preserving its API invoice from spiraling by month three is one other. The naive strategy to agent structure — appending each consumer message, commentary, and inner response to an endlessly rising array — quadratically will increase inference latency and linearly inflates token prices on each name. The foundation of this failure is treating the context window as a system of report.
There’s a distinction many engineers miss early on: Context is the ephemeral token payload despatched over the wire per request. State is the sturdy, serialized illustration of the agent’s progress. Conflate the 2 and also you’re paying in your database reads on each single inference name.
This tutorial covers seven of the commonest and expensive token-waste patterns in manufacturing agent techniques, together with the architectural fixes that tackle each.
1. Context Window Accumulation (The Append-Solely Entice)
Probably the most widespread mistake in agent design is treating the immediate array as a database. Each flip will get appended — consumer messages, software observations, intermediate reasoning, assistant responses. By flip 20, the agent is re-reading its whole operational historical past on each request, paying quadratically rising consideration prices to take action.
The repair: Implement a sliding context window with semantic rolling summarization. Go solely the final N turns verbatim. Compress older conversational turns right into a dense background abstract, and offload structural agent state to a deterministic retailer like SQLite or Redis relatively than injecting these values again into the immediate.
The catch: Summarization is inherently lossy. If an agent wants actual UUIDs, cryptographic hashes, or code snippets from early in a session, semantic compression will hallucinate them. Pair this sample with a strict key-value lookup software that retrieves actual strings when precision issues.
When to make use of it: This needs to be the default structure for any long-lived conversational agent or iterative reasoning loop anticipated to exceed 5 to 10 turns.
2. Uncompressed Device Outcome Ingestion
When an agent calls a third-party API, it usually receives a deeply nested JSON payload designed for machines, not language fashions. Dumping that uncooked response into the commentary context is likely one of the most avoidable sources of token waste. A single Stripe webhook payload or verbose AWS API response can devour hundreds of tokens, most of which comprise nothing the agent will ever purpose about.
The repair: Inject a middleware transformation layer between software execution and context injection. This layer strips null values, filters non-essential keys, and reformats deep JSON into dense YAML or structured Markdown. For logs, a deterministic pre-processing go can strip timestamps, thread IDs, and boilerplate earlier than the mannequin sees the information.
The catch: Aggressive filtering typically removes mandatory metadata, like pagination cursors. If the agent must paginate by way of a listing of outcomes, stripping the next_token subject to save lots of a handful of tokens will silently break the complete retrieval loop.
When to make use of it: Every time integrating third-party APIs — Stripe, Jira, AWS — that return verbose payloads optimized for machine consumption relatively than language mannequin reasoning.
3. Retrieval Thrash and “Grep-and-Dump”
In coding brokers and RAG-heavy techniques, a standard sample is utilizing naive textual content matching to search out related content material, then dumping whole recordsdata into the context window. The agent wants a single operate, so the orchestrator retrieves the complete 4,000-line file it lives in. It’s the retrieval equal of studying a whole encyclopedia to reply one query.
The repair: Shift to chunked, AST-aware (Summary Syntax Tree) retrieval. Throughout indexing, parse code right into a reside name graph. When the agent searches for a operate, the orchestrator queries the index and returns solely the precise operate signature, its docstring, and quick structural dependencies. That’s 300 tokens as a substitute of a whole file. Libraries like Tree-sitter make it simple to construct language-aware parsers that extract these structural models precisely.
The catch: Graph-aware retrieval requires steady, asynchronous indexing pipelines. If the vector index lags behind the repository’s predominant department, the agent will purpose confidently about stale state, try and name features that not exist, and burn output tokens working by way of the ensuing errors.
When to make use of it: Constructing coding brokers, RAG-heavy help bots, or any system interacting with quickly mutating, extremely structured codebases.
4. Static Device Schema Bloat
Most agent frameworks outline software schemas as soon as and inject all of them on each LLM name. For a small software registry that is innocent. For an agent with 30 or 50 instruments, the mannequin is studying hundreds of tokens of schema definitions on each request — together with schemas for instruments which might be fully irrelevant to the present activity part.
The repair: Implement context-aware software pruning ruled by a finite state machine. The agent’s present operational state dictates which instruments are injected. An agent in a “discovery” state receives solely search and browse instruments. As soon as it transitions to “execution,” it receives solely mutation and write instruments. The irrelevant schemas by no means devour tokens.
The catch: Dynamic software schemas intrude with immediate caching. Each time the software subset array modifications, the LLM supplier should recompute the KV cache for the affected immediate prefix, leading to larger latency and missed cache-hit reductions. This creates a direct stress with the recommendation in part six.
When to make use of it: Multi-agent architectures or solo brokers with massive software registries the place schema definitions alone exceed roughly 1,500 tokens of the context funds.
5. Unbounded Chain-of-Thought Loops
Autonomous brokers can get caught. A software name fails, the agent retries, the retry fails for a similar underlying purpose, and the agent retains producing reasoning and retry makes an attempt indefinitely. With out onerous limits, a single caught activity can devour tens of hundreds of output tokens — which most suppliers invoice at a better charge than enter tokens.
The repair: Implement an orchestrator-level circuit breaker. Implement strict most retry counts on software failures and cap the output token funds per motion. When the agent hits the brink, the orchestrator should intercept the loop, invoke a deterministic fallback, or escalate to a human within the loop relatively than permitting additional era. Frameworks like LangChain and LlamaIndex provide built-in retry and callback hooks that may function the inspiration for this type of circuit breaker logic.
The catch: Circuit breakers can false-positive on genuinely complicated duties. A respectable eight-step planning sequence requiring deep, multi-step search would possibly set off the restrict proper earlier than the ultimate synthesis step. Tuning retry thresholds requires observing actual agent traces, not guessing upfront.
When to make use of it: This can be a obligatory guardrail in any autonomous loop working in manufacturing. The price of a false constructive (a terminated activity) is sort of all the time decrease than the price of a runaway billing occasion.
6. Ignoring KV Cache and Immediate Prefixing
LLM suppliers cache the key-value representations of immediate prefixes to keep away from recomputing consideration over content material they’ve already processed. This delivers significant latency reductions and, at suppliers that go financial savings to customers, actual price reductions. Most brokers inadvertently defeat this by injecting dynamic variables (timestamps, consumer IDs, short-term reminiscence snapshots) on the high of the immediate, earlier than the static content material.
The repair: Construction each request with a strict static-to-dynamic gradient. Place large static content material (system prompts, organizational model guides, persistent schema definitions) on the absolute high of the request. By no means inject dynamic variables above the static payload. The cache boundary ought to fall on the finish of the longest static prefix you’ll be able to preserve. Each Anthropic’s immediate caching and OpenAI’s immediate caching documentation cowl the best way to construction requests to maximise cache hits for his or her respective APIs.
The catch: Not all suppliers help KV caching, and those who do implement TTLs — usually between 5 and fifteen minutes — that adjust by supplier. If the agent’s think-cycle is sluggish or the system is low-traffic, the cache will expire and also you’ll pay full worth for the prefix no matter how fastidiously you structured the immediate. Be mindful the strain this creates with part 4: dynamically pruning software schemas strikes the cache boundary and reduces cache-hit charges.
When to make use of it: Excessive-throughput, stateless brokers the place an identical massive system prompts are invoked hundreds of occasions per hour. Under that scale, the cache-miss danger could outweigh the architectural overhead.
7. Monolithic Routing (Utilizing Frontier Fashions for Easy Duties)
Frontier fashions — Opus-tier or GPT-4-class — are priced at a major premium over smaller options. Utilizing them to parse primary JSON, classify intents, or summarize easy utility logs is the equal of hiring a senior architect to file paperwork. The duty will get performed, however the cost-to-output ratio falls aside at scale.
The repair: Implement a cascaded LLM router. Use a quick, small mannequin — Haiku-tier or Gemini Flash-class — for intent classification, structural information extraction, and log summarization. Path to the frontier mannequin solely when complicated multi-step reasoning is explicitly required by the categorized intent. Open-source routing libraries like LiteLLM make it simpler to implement provider-agnostic routing logic with out rewriting API name scaffolding for every mannequin.
The catch: Small fashions are brittle when confronted with complicated or overlapping software schemas. If the classification layer misroutes a request attributable to inadequate reasoning capability, it’ll ship rubbish parameters to the frontier mannequin, producing quick failure and successfully doubling the token spend for that decision. The routing boundary should be positioned the place the duty complexity genuinely separates.
When to make use of it: Techniques with predictable, high-volume inputs the place structural sub-tasks could be cleanly decoupled from the core reasoning engine. In case your inputs are extremely variable or the intent boundary is ambiguous, cascaded routing introduces extra failure floor than it saves.
Two Further Patterns Value Watching
The seven objects above tackle the commonest failure modes, however two patterns that don’t seem on many checklists are price flagging.
Output token waste by way of unconstrained era. The checklist above focuses totally on enter token waste, however output tokens are usually billed at a better charge. When an agent is requested to extract structured information (a reputation and e-mail, say) and not using a constrained output format, the mannequin usually generates conversational preamble earlier than the precise values. Throughout hundreds of calls, this provides up. Utilizing provider-native structured output modes or tool-use schemas wherever the specified output is structured information relatively than prose eliminates this class of waste completely.
Redundant context injection. A surprisingly frequent manufacturing sample is injecting the identical info in a number of locations: as soon as within the system immediate, once more as a reminder in a latest user-turn injection, and infrequently a 3rd time as a software consequence affirmation. Every copy prices tokens, and when one copy is up to date whereas one other isn’t, the agent should reconcile conflicting variations. An audit go that treats every reality as having precisely one canonical injection level usually shaves 10-20% off complete enter tokens with no loss in activity efficiency.
Conclusion
Token optimization isn’t about being low cost. It’s about system stability. A bloated context payload interprets on to larger inference latency and a bigger floor space for retrieval failures and hallucinations. Constraining the context window to the minimal required for the duty forces extra deterministic habits, reduces orchestrator timeouts, and tightens the system’s failure area.
The patterns above aren’t mutually unique, and neither are their tradeoffs. Sections 4 and 6 pull in reverse instructions: dynamic software pruning saves tokens however undermines cache effectivity, whereas static prefixing maximizes cache hits however retains irrelevant schemas in view. The proper stability will depend on the software registry measurement, request quantity, and the supplier’s caching implementation. Actual manufacturing traces are the one dependable option to discover the place to attract the road.
By day 100 in manufacturing, token waste stops being a billing difficulty and turns into a knowledge high quality difficulty. Stale details accumulate in vector shops, episodic reminiscence fills with outdated API documentation, and brokers enter reasoning loops attempting to reconcile hallucinated state with manufacturing actuality. The architectural choices made in week one compound in each instructions.