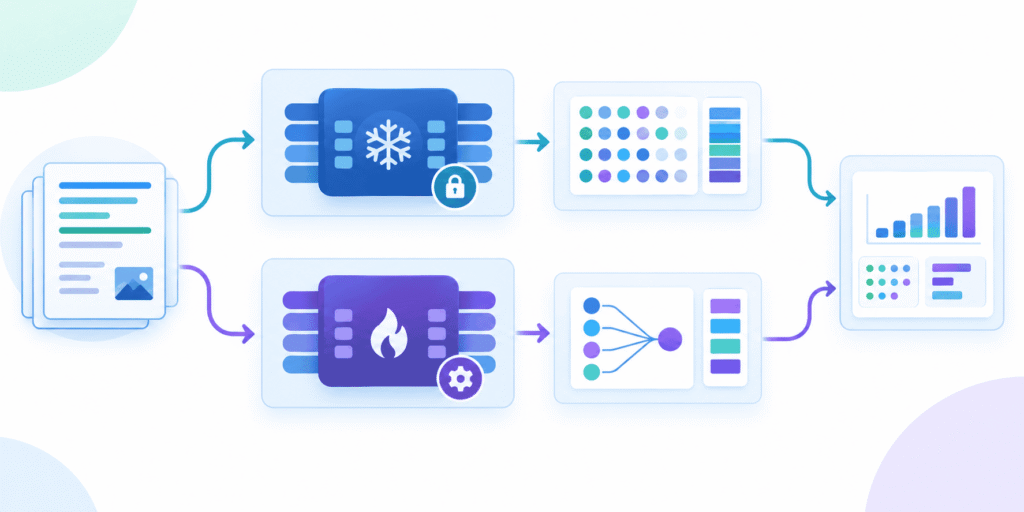
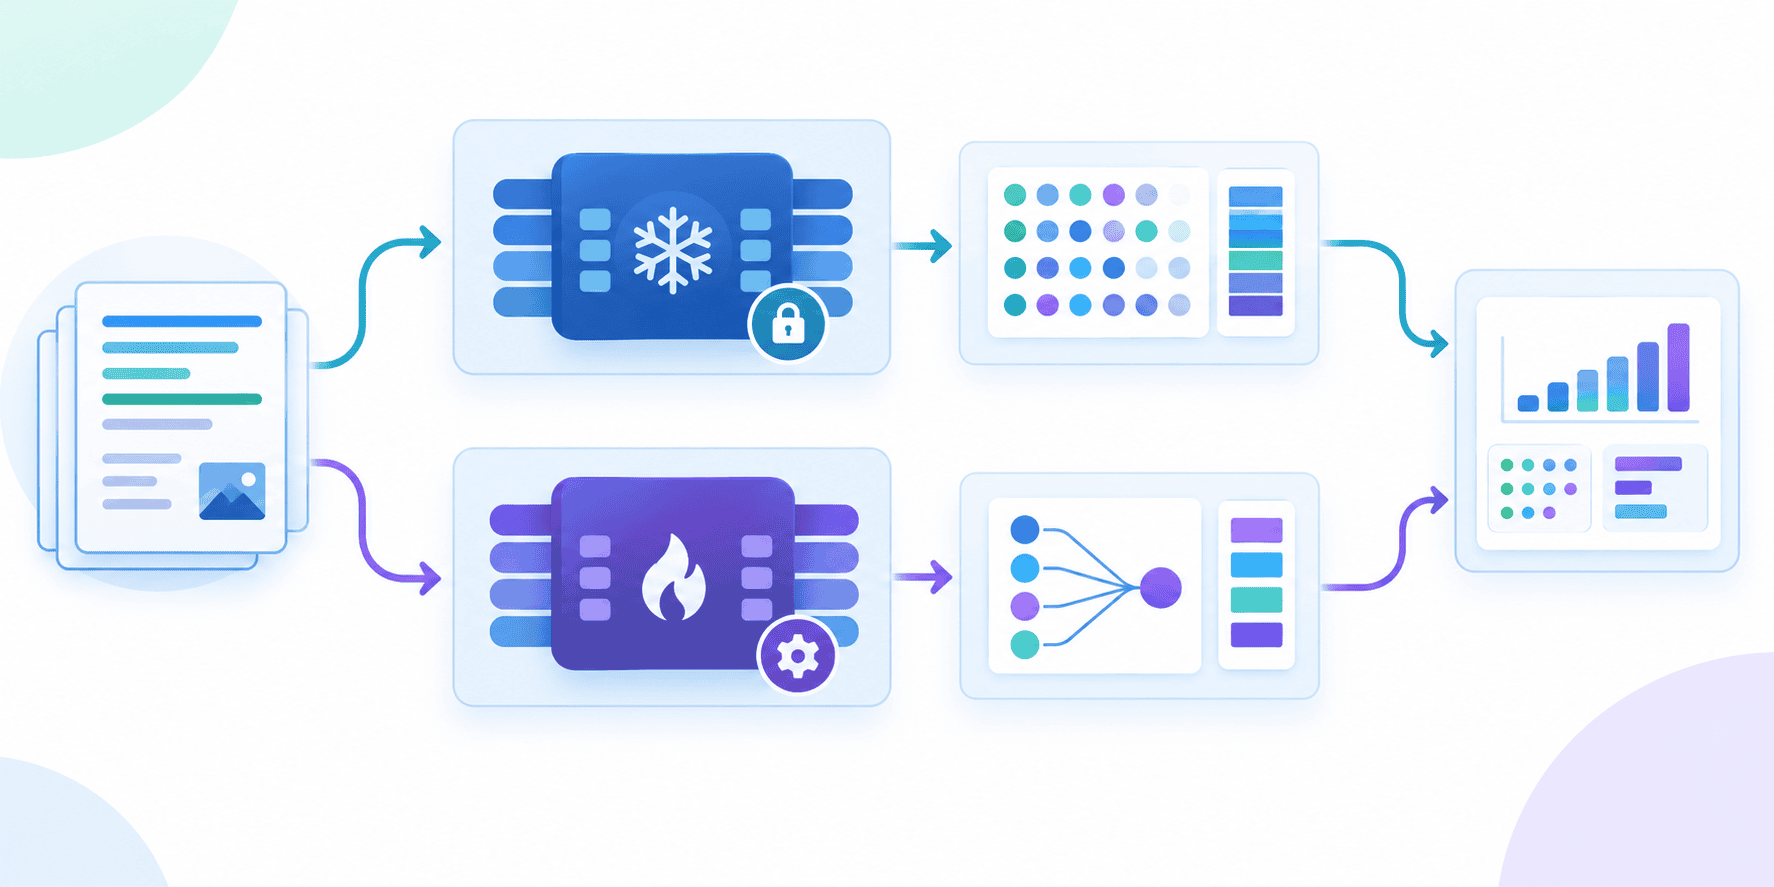
On this article, you’ll discover ways to examine two methods for adapting a big language mannequin to a selected area: fine-tuning with LoRA versus coaching a scikit-learn classifier on frozen embeddings.
Matters we are going to cowl embody:
- How frozen embeddings work as a light-weight different to full mannequin fine-tuning, and when this strategy is suitable.
- Methods to implement QLoRA fine-tuning utilizing the PEFT library with a Hugging Face mannequin and a classification head.
- How the 2 methods examine by way of coaching time and classification accuracy on an actual dataset.
Introduction
When adapting an LLM (a big language mannequin) to a selected area, the classical strategy picked by the machine studying neighborhood boils all the way down to fine-tuning the mannequin on a domain-specific dataset. However a query arises: is that this at all times essential? Or might different methods like utilizing frozen embeddings mixed with light-weight downstream classifiers on prime of the mannequin be a wiser strategy to undertake, particularly when constructing cost-friendly, compute-constrained functions?
This text presents a sensible comparability of fine-tuning a neighborhood LLM with LoRA (Low-Rank Adaptation, an algorithm for environment friendly weight updating) in opposition to coaching solely a downstream scikit-learn classifier on frozen embeddings. We cowl, analyze, and talk about when every technique is most well-liked based mostly on value and efficiency.
To take advantage of the sensible instance under, we advocate a primary degree of familiarity with LLMs, key processes like mannequin fine-tuning, and related libraries like Hugging Face’s transformers.
Preliminary Setup
In case you are working this sensible comparability on Google Colab, in the beginning, be sure you set the working setting to GPU (T4), because the code and strategies utilized in it are optimized for GPU use. You’ll solely want to put in the next libraries:
|
!pip set up –q –U bitsandbytes peft speed up consider |
In any other case, if you’re in a distinct Python setting, ensure to have scikit-learn, transformers, and datasets additionally put in earlier than continuing.
We begin by making a few of the imports wanted and loading a canonical dataset from the Hugging Face repository: ag_news, containing categorized information articles.
|
import torch import numpy as np import time from datasets import load_dataset from transformers import AutoTokenizer, AutoModelForSequenceClassification, BitsAndBytesConfig
# To make use of Llama-3 as a substitute, change this to “meta-llama/Meta-Llama-3-8B” MODEL_ID = “Qwen/Qwen2.5-1.5B”
print(“1. Loading dataset…”) dataset = load_dataset(“fancyzhx/ag_news”) # A tiny subset is used in order that the comparability might be run in minutes, not hours, on GPU train_subset = dataset[“train”].shuffle(seed=42).choose(vary(800)) test_subset = dataset[“test”].shuffle(seed=42).choose(vary(200)) |
Subsequent, we load the mannequin occasion and its related tokenizer, guaranteeing it’s configured with a classification head suitable with the precise downside (dataset) at hand, during which information articles are labeled into 4 doable courses:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 |
print(“2. Configuring Tokenizer…”) tokenizer = AutoTokenizer.from_pretrained(MODEL_ID) tokenizer.pad_token = tokenizer.eos_token # Essential for decoder-only fashions
print(“3. Loading Base Mannequin in 4-bit…”) bnb_config = BitsAndBytesConfig( load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_quant_type=“nf4” )
# Loading the mannequin with a classification head mannequin = AutoModelForSequenceClassification.from_pretrained( MODEL_ID, num_labels=4, quantization_config=bnb_config, device_map=“auto” ) mannequin.config.pad_token_id = tokenizer.pad_token_id |
Technique A: Frozen Embeddings & Scikit-learn
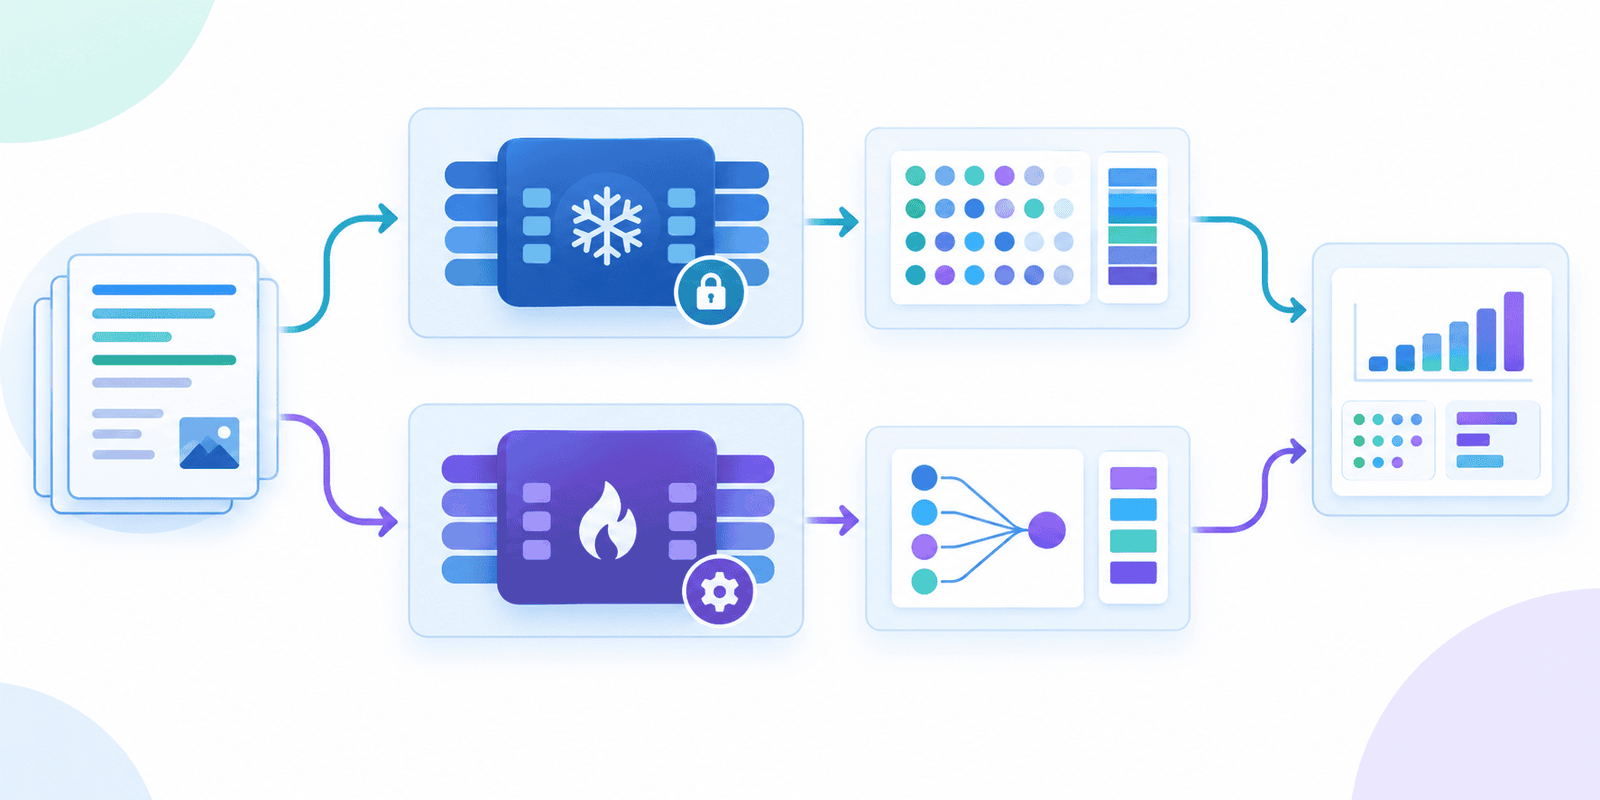
We begin by making an attempt out the choice to fine-tuning our mannequin. It really works as follows: as a substitute of retraining the LLM, we make it act strictly as a function extractor. We cross the textual content by this “frozen mannequin” (one during which weights can’t change) and extract the final hidden state (the embedding vector) for the ultimate token. These high-dimensional embeddings are then fed to an auxiliary mannequin — in different phrases, they’re used to coach a conventional light-weight classifier on prime of the frozen LLM.
Step one is defining a operate with the interior logic to acquire the frozen embeddings from enter texts:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 |
from sklearn.ensemble import RandomForestClassifier from sklearn.metrics import accuracy_score
def extract_embeddings(texts, batch_size=8): mannequin.eval() embeddings = []
for i in vary(0, len(texts), batch_size): batch = texts[i:i+batch_size] inputs = tokenizer(batch, return_tensors=“pt”, padding=True, truncation=True, max_length=128).to(mannequin.system)
with torch.no_grad(): # output_hidden_states=True forces the mannequin to return the uncooked vectors outputs = mannequin(**inputs, output_hidden_states=True) last_hidden_state = outputs.hidden_states[–1]
# Imply pooling: averaging the vectors throughout the sequence size, ignoring padding tokens masks = inputs[“attention_mask”].unsqueeze(–1).float() sum_embeds = torch.sum(last_hidden_state * masks, dim=1) mean_pooled = sum_embeds / torch.clamp(masks.sum(dim=1), min=1e–9)
embeddings.append(mean_pooled.cpu().numpy().astype(np.float32))
return np.concatenate(embeddings, axis=0) |
Subsequent, we name the operate passing our dataset pattern — already cut up into coaching and take a look at subsets — and acquire the frozen embeddings that shall be used to coach and take a look at a random forest classifier:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
print(“Extracting embeddings…”) start_time = time.time() X_train = extract_embeddings(train_subset[“text”]) X_test = extract_embeddings(test_subset[“text”]) y_train = train_subset[“label”] y_test = test_subset[“label”] embed_time = time.time() – start_time
print(“Coaching Scikit-Be taught Random Forest…”) clf = RandomForestClassifier(n_estimators=100, random_state=42) start_train_time = time.time() clf.match(X_train, y_train) sklearn_train_time = time.time() – start_train_time
preds = clf.predict(X_test) sklearn_acc = accuracy_score(y_test, preds)
print(f“n— Technique A Outcomes —“) print(f“Extraction Time: {embed_time:.1f}s”) print(f“Classifier Practice Time: {sklearn_train_time:.3f}s”) print(f“Accuracy: {sklearn_acc * 100:.1f}%”) |
Outcomes:
|
—– Technique A Outcomes —– Extraction Time: 96.5s Classifier Practice Time: 2.866s Accuracy: 82.0% |
Whereas it took practically 100 seconds to finish, the overwhelming majority of that point went to the function extraction course of — the classifier coaching itself was virtually immediate.
Let’s see whether or not the 82% take a look at classification accuracy yielded by this frozen embedding-driven classifier might be overwhelmed by a fine-tuned LLM.
Technique B: LoRA Wonderful-Tuning (QLoRA)
This technique makes use of Low-Rank Adaptation (LoRA): an optimized fine-tuning algorithm that freezes the huge pre-trained weights of the mannequin and injects trainable “adapter” weight matrices into the transformer layers. The complexity of the method boils all the way down to coaching these small adapter matrices, which usually account for simply 1-2% of the full mannequin dimension, whereas sustaining 4-bit precision to save lots of reminiscence.
The primary two steps are attaching the adapters to the bottom mannequin and getting ready the information for fine-tuning:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 |
from peft import LoraConfig, get_peft_model, prepare_model_for_kbit_training from transformers import TrainingArguments, Coach import consider
print(“1. Attaching LoRA Adapters to Base Mannequin…”) mannequin = prepare_model_for_kbit_training(mannequin) peft_config = LoraConfig( task_type=“SEQ_CLS”, r=16, lora_alpha=32, lora_dropout=0.05, target_modules=[“q_proj”, “v_proj”] # Goal consideration layers ) lora_model = get_peft_model(mannequin, peft_config) lora_model.print_trainable_parameters()
print(“n2. Getting ready Information for Coach…”) def tokenize_fn(examples): return tokenizer(examples[“text”], padding=“max_length”, truncation=True, max_length=128)
tokenized_train = train_subset.map(tokenize_fn, batched=True) tokenized_test = test_subset.map(tokenize_fn, batched=True)
accuracy_metric = consider.load(“accuracy”) def compute_metrics(eval_pred): predictions, labels = eval_pred predictions = np.argmax(predictions, axis=1) return accuracy_metric.compute(predictions=predictions, references=labels) |
Observe that the results of integrating the adapter matrices into our base LLM is saved in a brand new mannequin variable named lora_model.
We then conduct the core fine-tuning course of configured as LoRA — it requires TrainingArguments and Coach objects:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 |
print(“n3. Beginning QLoRA Wonderful-Tuning…”) training_args = TrainingArguments( output_dir=“./outcomes”, per_device_train_batch_size=8, per_device_eval_batch_size=8, learning_rate=2e–4, num_train_epochs=3, eval_strategy=“epoch”, logging_strategy=“epoch”, optim=“paged_adamw_8bit”, # Saves VRAM by offloading optimizer states fp16=True, report_to=“none” )
coach = Coach( mannequin=lora_model, args=training_args, train_dataset=tokenized_train, eval_dataset=tokenized_test, compute_metrics=compute_metrics, )
start_time = time.time() coach.prepare() lora_train_time = time.time() – start_time
print(“n4. Evaluating QLoRA Mannequin…”) eval_results = coach.consider() lora_acc = eval_results[“eval_accuracy”]
print(f“n— Technique B Outcomes —“) print(f“LoRA Practice Time: {lora_train_time:.1f}s”) print(f“Accuracy: {lora_acc * 100:.1f}%”) |
Outcomes (you will note extra detailed outcomes per coaching epoch should you execute the code):
|
—– Technique B Outcomes —– LoRA Practice Time: 300.3s Accuracy: 87.0% |
Classification efficiency does enhance after we adapt our mannequin to the precise downside the standard method: by fine-tuning it. That enchancment comes at a value, nonetheless — your entire course of took thrice as lengthy, with all of that overhead going into the coaching course of itself. For bigger datasets, this distinction in time could turn out to be considerably extra pronounced.
Verdict and Conclusion
Feeding frozen embeddings to an auxiliary scikit-learn mannequin is the really helpful strategy when searching for fast coaching and minimal compute overhead whereas avoiding spine overfitting. QLoRA fine-tuning, against this, is the higher selection when closing the accuracy hole is important to your area, or when the mannequin must study deeply embedded domain-specific nuances.
This calculus modifications for purely generative duties like textual content and code technology, the place mannequin adaptation — equivalent to fine-tuning — is usually essential for specialised behaviors. That mentioned, the frozen embedding technique can generally be a viable different for generative workflows in free-tier deployments the place most efficiency is barely negotiable.